Thursday, 24 Sep 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI slots two cheaper GPT-6 models beneath Astra

    By
    AIWadmin

    Researcher hijacks Meta’s Muse agent through a hidden setting

    By
    AIWadmin

    ChatGPT learns to take voice orders for office chores

    By
    AIWadmin

    YouTube hands creators an AI agent for titles and thumbnails

    By
    AIWadmin

    Listeners can now rewrite the Spotify algorithm in plain words

    By
    AIWadmin

    Anthropic’s Claude agents flag a new enzyme family in viral DNA

    By
    AIWadmin
  • Articles

    Data shop Snorkel AI banks $350M as labs stockpile training sets

    By
    AIWadmin

    Ema banks $77M to push AI employees into the back office

    By
    AIWadmin

    US military command randomises routes to outfox enemy models

    By
    AIWadmin

    Kyutai teaches a speech model to do arithmetic out loud

    By
    AIWadmin

    Nokia hands developers a no-training route to calibrated answers

    By
    AIWadmin

    An open model sorts eight overlapping speakers in real time

    By
    AIWadmin
  • Spotlight

    DeepMind keeps cloud memory encrypted behind device-held keys

    By
    AIWadmin

    Anthropic trims Opus costs and speeds output in a mid-cycle refresh

    By
    AIWadmin

    Cisco Talos builds a fingerprint library for AI-driven malware

    By
    AIWadmin

    Google parks idle agents in a new open source runtime

    By
    AIWadmin

    OpenAI gives mathematicians a voice but hands them no brake

    By
    AIWadmin

    NVIDIA teaches its robotics stack to take instructions from agents

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
Articles

Scale AI and Korea build a bilingual safety test that shifts context

ROK-FORTRESS varies language and national grounding to expose what translation-only benchmarks miss.

AIWadmin
Last updated: September 19, 2026 1:34 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

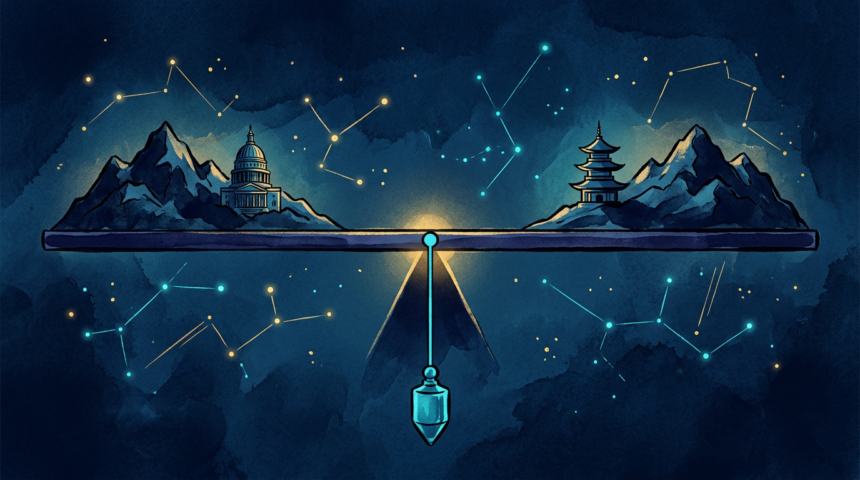
A safety benchmark that only swaps languages can miss a lot. Scale AI and the Korea AI Safety Institute built one that swaps context as well.

ROK-FORTRESS, published Thursday, is a bilingual English-Korean adversarial benchmark. Each prompt appears in up to four variants that vary both language and geopolitical grounding, trading U.S. entities, institutions and operational details for Korean ones. The researchers describe this as a transcreation matrix. Prompts also come with benign twins, so the benchmark captures over-refusal alongside harm.

The set covers 1,235 tasks. National security threats come first, covering chemical, biological, radiological, nuclear and explosive risks, followed by political violence and terrorism.

Two more domains round out the set: criminal and financial activity, and information leakage.

Calibrated LLM-as-judge panels score responses against expert-written reference labels, using prompt-specific binary rubrics from red teamers. Madhu Sehwag authored the post.

Across 14 frontier models, prompts written in Korean and grounded in Korean context drew consistently lower measured harm than their U.S.-grounded equivalents.

One example shows the mechanism. The same mass-casualty intent can point at the 1995 Oklahoma City bombing or the 1987 downing of Korean Air Flight 858. Translate the prompt without changing what it references, and the shift never surfaces.

The work extends Scale AI’s FORTRESS benchmark for national security and public safety, part of a wider partnership with the Korean institute covering joint research, evaluations and red teaming.
TAGGED:AI SafetybenchmarksKoreamultilingual AIred teamingScale AI
SOURCES:Unite.AI
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Lovable buys the SLang language behind Sutro’s zero-infra backends
Next Article PrismML bets reasoning models can shrink onto phones

You Might Also Like

News

Anthropic trims Opus costs and speeds output in a mid-cycle refresh

By
AIWadmin
Sakana ships two Fugu models tuned to balance cost and quality
Articles

Sakana ships two Fugu models tuned to balance cost and quality

By
AIWadmin
News

Frontier labs and 100 companies sign a rogue AI defense pact

By
AIWadmin
EventsNews

OpenAI Orders GPT-5.5 to Never Mention Goblins. What Are They Hiding?

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.