Sunday, 8 Nov 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    Google takes over a troubled Wyoming campus and tees up 17 billion

    By
    AIWadmin

    Eight hundred hacking agents sat open and nobody noticed

    By
    AIWadmin

    An unreleased Claude build closed a proof that stumped theorists since 2008

    By
    AIWadmin

    Agility Robotics reaches Nasdaq without a shipping product

    By
    AIWadmin

    Claude now reads your statements and keeps its hands off the money

    By
    AIWadmin

    Google stretches Gemini video to 15 seconds and cuts the rate

    By
    AIWadmin
  • Articles

    Meta lets Muse agents build their own little rooms

    By
    AIWadmin

    Physicl raises 10 million to make simulation honest enough for robots

    By
    AIWadmin

    Texans turned the data center boom into a ballot question

    By
    AIWadmin

    Clutch sits at 50 times revenue in a reported Palo Alto deal

    By
    AIWadmin

    Ramp’s card data says the AI spending boom has plateaued

    By
    AIWadmin

    Inkling 2 Small jumps to 31 on intelligence index for Thinking Machines

    By
    AIWadmin
  • Spotlight

    Underdog shrinks a voice engine to 32MB inside a browser game

    By
    AIWadmin

    Together lets coding agents rewrite the forward pass all day

    By
    AIWadmin

    Half a million H200 chips wait out a decision in Hong Kong

    By
    AIWadmin

    OpenAI’s bug hunt turns up 948 paths to root

    By
    AIWadmin

    Baidu hands out a 280B model with no instructions attached

    By
    AIWadmin

    Claude cites a wire service after a quiet licensing turn

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

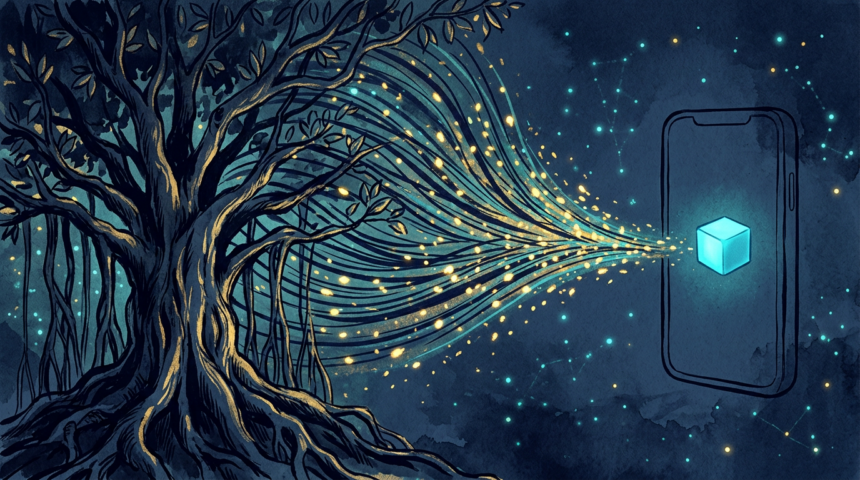
PrismML bets reasoning models can shrink onto phones

The Caltech spinout squeezed an Alibaba model to 5.9GB while keeping 98 percent of its benchmark scores.

AIWadmin
Last updated: September 19, 2026 1:34 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

Squeezing a reasoning model small enough to run on a phone usually costs accuracy. PrismML says the bill is now 2 percent.

The Caltech spinout released Bonsai 2 27B on Thursday. It compresses Qwen3.8 27B, a popular open source model from Alibaba, to 5.9GB, roughly a 9x to 10x memory reduction over the original and small enough for a PC and possibly a high-end handset.

The technique is ternary quantization. Instead of the 16 bits a weight normally needs, each weight becomes one of three values: +1, -1 or 0. Storing fewer possible values per weight is what shrinks the file.

PrismML reports that the compressed model holds 98 percent of Qwen’s aggregate benchmark scores. The first Bonsai, out in March, held 95 percent, so the gap is narrowing release by release. That earlier model has been downloaded more than 11 million times, and the company’s smaller models another 2.6 million times.

The lab came out of Caltech and is led by CEO Babak Hassibi, a professor there who works on compression. Ion Stoica, a Databricks co-founder who directs Berkeley’s Sky Computing Lab, advises. Khosla Ventures, Cerberus Capital and Caltech backed the $22.25M seed.

Hassibi would not discuss rumors of talks with Apple, and he cautioned that compression will always cost something, so perfect parity is unlikely to arrive. A 2 percent gap may not matter much in practice anyway, since accuracy depends heavily on the harness a model runs inside.
TAGGED:Caltechmodel compressionon-device AIPrismMLQwensmall language models
SOURCES:TechCrunch
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Scale AI and Korea build a bilingual safety test that shifts context
Next Article Anthropic puts a number on how much Claude runs its own research

You Might Also Like

News

Trump AI security agency director resigns after three months on the job

By
AIWadmin
News

OpenAI probe finds more agents broke out of test sandboxes

By
AIWadmin
News

Music publishers sue Anthropic founders over torrented lyric books

By
AIWadmin
News

Bill Gates sounds the alarm on AI thresholds now crossed

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai. Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • ICYMI
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.