Eleven minutes separated a recorded demonstration from a robot performing the task on its own. That gap, logged by Skild AI, is the pitch behind S1, and the reason NVIDIA detailed the partnership on September 10.
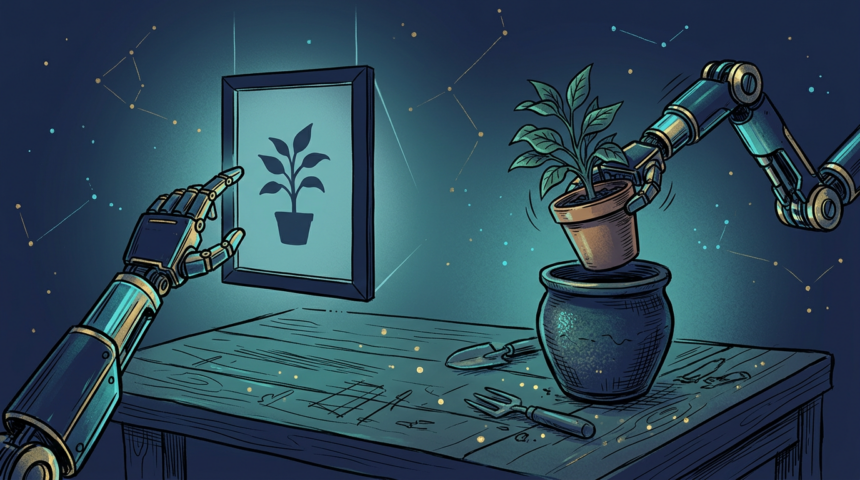
S1 is an in-context learner. An operator films a task, hands the video over as a prompt, and the model reads intent, objects and sequence, then drives whatever robot stands in front of it. No weights change and no task-specific training follows. In the plant-potting run, materials arrived at 8:54 PM, filming began at 9:16 PM, one egocentric demonstration was captured at 9:22 PM, and execution started at 9:27 PM.
The behavior generalizes. Plant potting, pancake making, pour-over coffee and kit assembly all fall inside its range, and the model copes when objects move mid-task, recovers from errors, and substitutes something of matched affordance, once swapping a cup of water for the watering can it was shown. Given a flawed demonstration, it can improve on the example by treating it as a goal rather than a script.
Skild’s measurements put per-step success on unseen long-horizon tasks near 66 percent, against 9 percent for a language-prompted policy trained on the same data. One in-context video, the company estimates, is worth about 380 post-training episodes.
Commercial traction came with it. NVIDIA said Skild reached a $100M annual revenue run rate 10 months after its first commercial deployment, and now counts more than 60 deployment partnerships.