Thursday, 24 Sep 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI slots two cheaper GPT-6 models beneath Astra

    By
    AIWadmin

    Researcher hijacks Meta’s Muse agent through a hidden setting

    By
    AIWadmin

    ChatGPT learns to take voice orders for office chores

    By
    AIWadmin

    YouTube hands creators an AI agent for titles and thumbnails

    By
    AIWadmin

    Listeners can now rewrite the Spotify algorithm in plain words

    By
    AIWadmin

    Anthropic’s Claude agents flag a new enzyme family in viral DNA

    By
    AIWadmin
  • Articles

    Data shop Snorkel AI banks $350M as labs stockpile training sets

    By
    AIWadmin

    Ema banks $77M to push AI employees into the back office

    By
    AIWadmin

    US military command randomises routes to outfox enemy models

    By
    AIWadmin

    Kyutai teaches a speech model to do arithmetic out loud

    By
    AIWadmin

    Nokia hands developers a no-training route to calibrated answers

    By
    AIWadmin

    An open model sorts eight overlapping speakers in real time

    By
    AIWadmin
  • Spotlight

    DeepMind keeps cloud memory encrypted behind device-held keys

    By
    AIWadmin

    Anthropic trims Opus costs and speeds output in a mid-cycle refresh

    By
    AIWadmin

    Cisco Talos builds a fingerprint library for AI-driven malware

    By
    AIWadmin

    Google parks idle agents in a new open source runtime

    By
    AIWadmin

    OpenAI gives mathematicians a voice but hands them no brake

    By
    AIWadmin

    NVIDIA teaches its robotics stack to take instructions from agents

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

Chipmaker d-Matrix books a rack slot in NVIDIA’s AI factory plan

Raptor inference XPUs will hook into MGX racks through NVLink Fusion, splitting inference work between GPUs and custom silicon.

AIWadmin
Last updated: September 10, 2026 9:55 pm
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

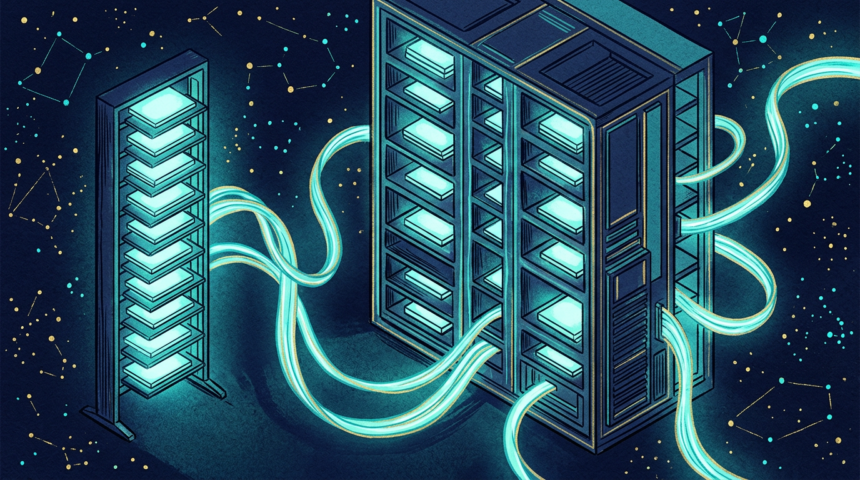
Racks built around d-Matrix’s Raptor inference chips should be available integrated into NVIDIA systems by the fourth quarter of 2027, the two companies said on September 10, under a multi-year roadmap that routes the silicon through NVLink Fusion and the MGX rack architecture.

The division of work is the interesting part. Rather than replacing GPUs, d-Matrix expects operators to split a single inference job by stage, running the compute-heavy prefill phase on NVIDIA accelerators and the latency-sensitive decode phase on its own XPUs. Raptor racks are designed to sit beside GPU systems including Vera Rubin NVL72.

Applications in the company’s sights are the ones where speed is worth money: coding assistants, real-time chatbots, voice agents. The trays are modular and cable-free, built through the MGX supply chain, with custom connectivity supplied by Astera Labs.

NVIDIA’s numbers for the platform put XPU-to-XPU latency three times lower than commodity Ethernet, packet rates 10 times higher, and all-to-all bandwidth at 3 TB per second per XPU over sixth-generation NVLink.

Chief executive Sid Sheth framed the decision around limited capital, time and energy, arguing the integration lowers the risk of reaching large-scale deployment. Jensen Huang’s statement cast the same deal from NVIDIA’s side, describing a path for partners to attach custom silicon while giving customers more accelerator choice.
TAGGED:AI Chipsd-MatrixData Center HardwareInferenceNvidiaNVLink
SOURCES:NVIDIA BlogUnite.AI
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Skild AI hits $100M run rate with robots that learn
Next Article Ayar Labs raises another $150M to push optics past copper

You Might Also Like

News

AMD’s open 16B MoE model tops fully open rivals on benchmarks

By
AIWadmin
News

Sixfold memory cost jump pushes OVHcloud to reprice its servers

By
AIWadmin
News

Taiwan Rallies Democracies to Unite on Chips, AI, and Drones

By
Zoe Chang
News

Skild AI hits $100M run rate with robots that learn

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.