Wednesday, 4 Nov 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    An AI edited a small model’s weights and doubled its math score

    By
    AIWadmin

    Thieves are renting out cloud AI keys pilfered from enterprises

    By
    AIWadmin

    Britain’s cyber agency sets a two-year clock on AI-written ransomware

    By
    AIWadmin

    Anthropic’s compute bill now eats a bigger share of every dollar

    By
    AIWadmin

    A benchmark asks agents to size switchboards and check roof decks

    By
    AIWadmin

    Apple will stop treating a chatbot boyfriend as an app for kids

    By
    AIWadmin
  • Articles

    Trajectory raises $45M to let specialists retrain models without researchers

    By
    AIWadmin

    Switching off AI in schools now means switching off Google search

    By
    AIWadmin

    CrowdStrike buys two agent monitors and ships a kill switch

    By
    AIWadmin

    SemiAnalysis built a benchmark no frontier model can pass

    By
    AIWadmin

    A British chip startup reaches a $6.5B value before shipping a wafer

    By
    AIWadmin

    Seoul puts $16B behind chips and its own frontier models

    By
    AIWadmin
  • Spotlight

    Envision pushes 800-volt power straight into a working AI campus

    By
    AIWadmin

    42AI leaves stealth with $62.5M to model how people decide

    By
    AIWadmin

    Tohoku and Aisin stash a whole model beside the arithmetic

    By
    AIWadmin

    Western startups are editing Chinese models until they sound American

    By
    AIWadmin

    Omen AI buys Aquatic Labs to watch what cools the racks

    By
    AIWadmin

    LG CNS hands over a 30-megawatt AI hall in Jakarta

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

A benchmark asks agents to size switchboards and check roof decks

Google and Mercor opened 29 of 85 engineering tasks to the public, and the best model still scores below half marks.

AIWadmin
Last updated: November 4, 2026 1:49 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

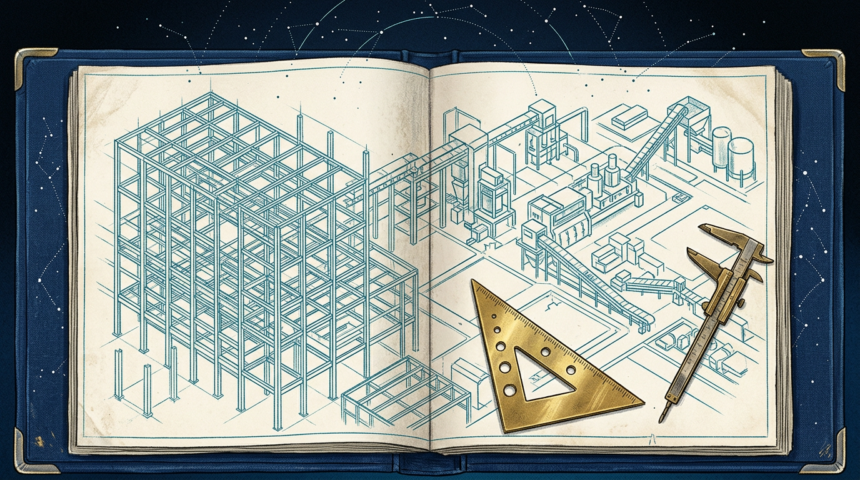
Most agent benchmarks test office work. Google’s AI and Infrastructure team, working with data vendor Mercor, built one around the jobs that produce physical things.

Contents
What a task looks likeThe scores stay low

Physical-Engineering’s Last Exam holds 85 long-horizon tasks across mechanical, electrical, civil and structural engineering. This week 29 of them, plus the grading tools and evaluation container, went public alongside an open competition and leaderboard.

What a task looks like

Each runs in a project folder averaging 61 files: PDFs, spreadsheets, correspondence, superseded revisions, and drawings in DXF, DWG or IFC format. The agent must work out which documents govern, then issue deliverables a licensed engineer could review, such as calculation workbooks, equipment schedules and 3D models.

Examples include sizing steel roof decking under snow-drift and shear loads, laying out a phased campus around wetland buffers, and picking heat-rejection equipment against a 25-year cost objective.

Practising engineers wrote 44 tasks end to end. In the other 41, an adversarial pipeline built the environments and graders from real documentation, then experts raised the difficulty.

The scores stay low

On the private 56-task set, no model cleared 50 percent in its native harness. Claude Opus 5.5 in Claude Code led at 48.3 percent, followed by GPT-6 Astra at 45.8 and Claude Sonnet 5.5 at 43.5. Several open models landed in single digits.

The leader spent roughly 27 million tokens and 63 minutes per task. Grading combines code compliance with an economic objective, so a design can pass every check and still lose points for costing more to install.

Google says solvers ran without internet access. The remaining 56 tasks stay hidden for the competition.
TAGGED:AI AgentsbenchmarksEngineeringGoogle CloudMercormodel evaluation
SOURCES:Google CloudMercorarXiv
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Apple will stop treating a chatbot boyfriend as an app for kids
Next Article Anthropic’s compute bill now eats a bigger share of every dollar

You Might Also Like

News

Serval takes $150M to push automation agents past IT desks

By
AIWadmin
News

Anthropic says its bundling strategy is what keeps enterprises paying

By
AIWadmin
News

DeepMind’s cyclone model beats forecasters by a day, then goes open

By
AIWadmin
News

Abbott glucose streams feed Gemini health coaching at Google

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.