Thursday, 29 Oct 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI’s Berlin pitch was about owning the runtime, not the model

    By
    AIWadmin

    A one-researcher model lab ships a 10M-token coding engine

    By
    AIWadmin

    Liquid AI branches six small models off one backbone

    By
    AIWadmin

    Google gives language models a sleep cycle to remember new facts

    By
    AIWadmin

    Harvey clears the federal security bar for legal AI

    By
    AIWadmin

    Musk predicts a cull of 200 neoclouds as debt markets close

    By
    AIWadmin
  • Articles

    Google hands Oracle the keys to sell its TPUs

    By
    AIWadmin

    Airbnb drags recommendation data from two days old to twenty seconds

    By
    AIWadmin

    Android Studio opens its doors to Claude, Codex and 40 other agents

    By
    AIWadmin

    A Delaware plan would let software run companies with nobody in charge

    By
    AIWadmin

    OpenAI halves its agent pricing with a cheaper vision model

    By
    AIWadmin

    Claude for Legal now checks its own citations first

    By
    AIWadmin
  • Spotlight

    Circuit Mind puts a swarm of agents on schematic review

    By
    AIWadmin

    Upwind turns down a takeover and raises more instead

    By
    AIWadmin

    DeepMind keeps Gemini 4 Carbon behind a cyber defenders gate

    By
    AIWadmin

    Nvidia folds three speech jobs into a single open model

    By
    AIWadmin

    An inference cloud bets on rival silicon while the bears circle

    By
    AIWadmin

    Publishing staff threw a party for an AI assistant that died

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
Articles

Google frees the GPU engine sitting under its on-device AI runtime

ML Drift hides Metal, OpenCL, OpenGL ES and WebGPU behind one layer and already ships inside Chrome and Photos.

AIWadmin
Last updated: October 26, 2026 1:23 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

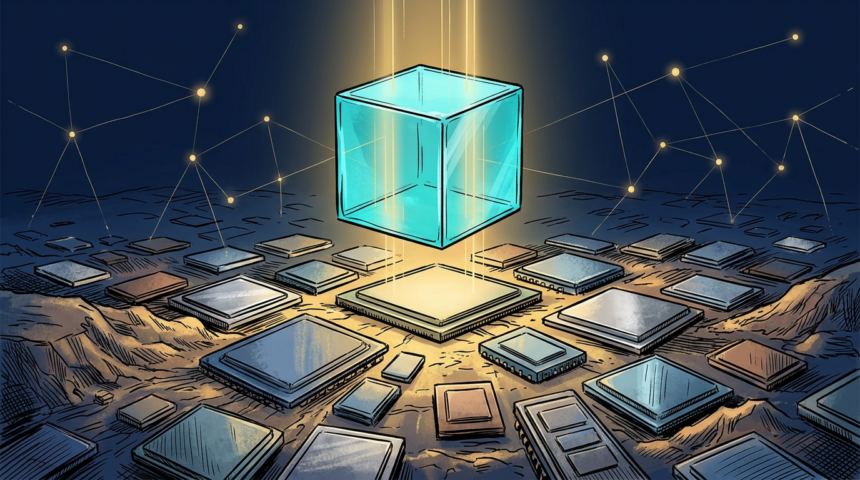
Google has open-sourced ML Drift under Apache 2.0, the GPU acceleration engine beneath its LiteRT runtime for on-device inference. The pitch is portability: one layer that talks to whatever graphics hardware a phone, laptop or browser happens to offer.

Developers currently pick their way through Metal on Apple hardware, OpenCL on Android, OpenGL ES on older devices and WebGPU in browsers. ML Drift absorbs those differences so the same model runs across them, from computer vision and audio through to generative workloads.

Underneath, it adds unified shaders through tensor virtualization, extensible custom operators and support for five-dimensional tensors. Google also tuned for GPUs from Arm, Intel and Qualcomm.

Desktop inference gets a path too. On Windows and Linux it reaches hardware through Dawn, Chromium’s WebGPU implementation, which avoids writing separate DirectX and Vulkan paths. Metal remains native on macOS.

Google benchmarked with Gemma models on workstation-class machines and reports 12 percent lower memory overhead than other frameworks, including llama.cpp and MLX LM. It also points out that the engine is already in production at scale, powering segmentation effects in YouTube Shorts, computational photography in Photos, and calling in Meet.

Published gains range from up to 40 percent lower frame latency on Android and iOS segmentation to roughly two seconds saved in photo pipelines and 30 percent faster edits in Adobe Lightroom and Photoshop.

Open-sourcing it lets teams build custom runtimes on the same foundation rather than wait for a vendor path.
TAGGED:AI InferenceGoogleLiteRTon-device AIopen source AIWebGPU
SOURCES:InfoQ
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Hugging Face teaches a chat model to read raw genetic code
Next Article Stanford and Berkeley shrink the first pass over long prompts

You Might Also Like

News

Volantis lands $88M to break AI’s memory wall with light

By
AIWadmin
News

A subreddit bans AI projects and touches off a revolt

By
AIWadmin
News

Frontier labs and 100 companies sign a rogue AI defense pact

By
AIWadmin
News

Aachen court makes Google answer for its AI summaries

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.