In a standard decoder-only language model, nothing computed at the last layer of one token reaches the first layer of the next. Positions communicate only through attention over cached keys and values.
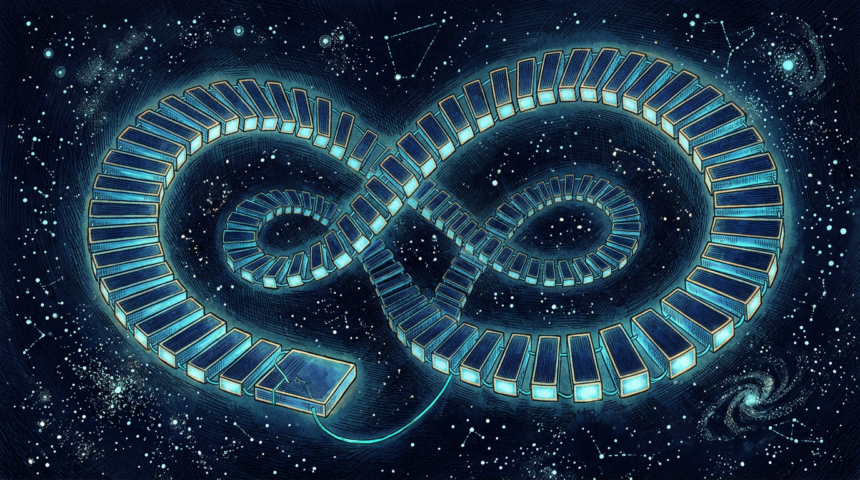
A Princeton researcher’s technical report proposes closing that loop. The Recurrent Looped Transformer carries the decoder’s final hidden state and its layerwise sliding-window attention cache forward, so working on a token can reuse whatever the previous token concluded.
The design fixes 96 blocks per token while leaving temporal depth unbounded. Because the loop reuses weights already present in the stack, the parameter count does not grow with the number of passes.
That shape matters for long-horizon work. Chain-of-thought reasoning and agent loops spend compute on repeated forward passes. A recurrent decoder folds some of that repetition into the architecture itself.
The report is a proposal, not a trained frontier system. No large-scale results or head-to-head benchmark wins were published with it, so practical gains remain unproven.