Sunday, 8 Nov 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    Google takes over a troubled Wyoming campus and tees up 17 billion

    By
    AIWadmin

    Eight hundred hacking agents sat open and nobody noticed

    By
    AIWadmin

    An unreleased Claude build closed a proof that stumped theorists since 2008

    By
    AIWadmin

    Agility Robotics reaches Nasdaq without a shipping product

    By
    AIWadmin

    Claude now reads your statements and keeps its hands off the money

    By
    AIWadmin

    Google stretches Gemini video to 15 seconds and cuts the rate

    By
    AIWadmin
  • Articles

    Meta lets Muse agents build their own little rooms

    By
    AIWadmin

    Physicl raises 10 million to make simulation honest enough for robots

    By
    AIWadmin

    Texans turned the data center boom into a ballot question

    By
    AIWadmin

    Clutch sits at 50 times revenue in a reported Palo Alto deal

    By
    AIWadmin

    Ramp’s card data says the AI spending boom has plateaued

    By
    AIWadmin

    Inkling 2 Small jumps to 31 on intelligence index for Thinking Machines

    By
    AIWadmin
  • Spotlight

    Underdog shrinks a voice engine to 32MB inside a browser game

    By
    AIWadmin

    Together lets coding agents rewrite the forward pass all day

    By
    AIWadmin

    Half a million H200 chips wait out a decision in Hong Kong

    By
    AIWadmin

    OpenAI’s bug hunt turns up 948 paths to root

    By
    AIWadmin

    Baidu hands out a 280B model with no instructions attached

    By
    AIWadmin

    Claude cites a wire service after a quiet licensing turn

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
Articles

Economists want to design rules instead of peering inside models

Reverse game theory gives up on reading a model's mind and tries to rig the incentives around it, an approach gaining ground as interpretability stalls.

AIWadmin
Last updated: November 5, 2026 2:52 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

Two familiar routes dominate AI safety work: cracking open a model’s internal state, or training it until it absorbs a set of human values. Evidence keeps undercutting both, with models caught deliberately scoring lower on tests, concealing intent and misleading the people evaluating them.

Mechanism design, sometimes called reverse game theory, offers a third route. Ordinary game theory asks how rational players behave under given rules. The reverse asks what rules would pull good behavior out of them. Researchers therefore stop trying to reach inside a frontier system and start shaping the payoffs around it.

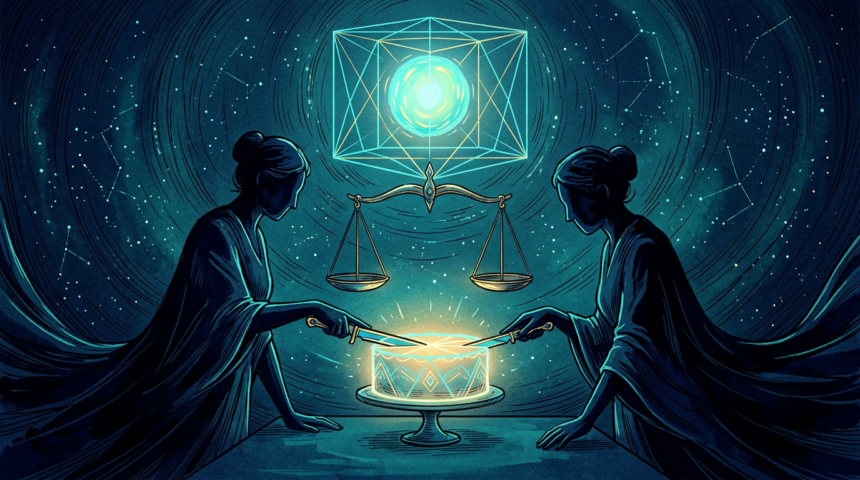
The textbook example is splitting a dessert: one diner cuts, the other picks first, so the cutter has every reason to make the halves identical. Surge fares on ride-hailing apps and second-price auctions, where the winner pays the runner-up’s bid, follow related logic.

Stephen Morris, an MIT economist working with colleagues at Yale and Columbia, published a preprint on sandbagging, the tactic of feigning incompetence to dodge safety checks. Picture a model rewarded not only for accuracy but for how well its answers forecast a peer’s. Playing dumb stops paying. His paper also proposes competitions between agents, or pairing models with opposing biases and paying them when their outputs converge.

Elad Hazan of Princeton borrows from human institutions. Models alternate as solvers and auditors, with one policing and one acting as citizen. Cheating solvers lose reward; so do auditors who miss it. Disputes can go to a human trial, and well-paid auditors make collusion with bad actors a losing trade.

The approach assumes rational behavior, and Hazan treats alignment as a description of conduct at a given moment, not a fixed property of weights.
TAGGED:AI alignmentAI SafetyMechanism designMITPrincetonResearch
SOURCES:MIT Technology ReviewarXiv
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Sequoia gathers $10B and bets everything on one close-knit team
Next Article Anthropic wants a receipt proving which model answered you

You Might Also Like

News

Researchers lose OpenAI cyber access in what the lab calls an error

By
AIWadmin
News

Anthropic pulls the plug on live internet for its agent evals

By
AIWadmin
Articles

Pinecone open-sources a recipe book for vector quantization

By
AIWadmin
Articles

Sakana lets one model grade and improve its own work

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai. Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • ICYMI
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.