Sunday, 8 Nov 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    Google takes over a troubled Wyoming campus and tees up 17 billion

    By
    AIWadmin

    Eight hundred hacking agents sat open and nobody noticed

    By
    AIWadmin

    An unreleased Claude build closed a proof that stumped theorists since 2008

    By
    AIWadmin

    Agility Robotics reaches Nasdaq without a shipping product

    By
    AIWadmin

    Claude now reads your statements and keeps its hands off the money

    By
    AIWadmin

    Google stretches Gemini video to 15 seconds and cuts the rate

    By
    AIWadmin
  • Articles

    Meta lets Muse agents build their own little rooms

    By
    AIWadmin

    Physicl raises 10 million to make simulation honest enough for robots

    By
    AIWadmin

    Texans turned the data center boom into a ballot question

    By
    AIWadmin

    Clutch sits at 50 times revenue in a reported Palo Alto deal

    By
    AIWadmin

    Ramp’s card data says the AI spending boom has plateaued

    By
    AIWadmin

    Inkling 2 Small jumps to 31 on intelligence index for Thinking Machines

    By
    AIWadmin
  • Spotlight

    Underdog shrinks a voice engine to 32MB inside a browser game

    By
    AIWadmin

    Together lets coding agents rewrite the forward pass all day

    By
    AIWadmin

    Half a million H200 chips wait out a decision in Hong Kong

    By
    AIWadmin

    OpenAI’s bug hunt turns up 948 paths to root

    By
    AIWadmin

    Baidu hands out a 280B model with no instructions attached

    By
    AIWadmin

    Claude cites a wire service after a quiet licensing turn

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

Chipmaker d-Matrix books a rack slot in NVIDIA’s AI factory plan

Raptor inference XPUs will hook into MGX racks through NVLink Fusion, splitting inference work between GPUs and custom silicon.

AIWadmin
Last updated: September 10, 2026 9:55 pm
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

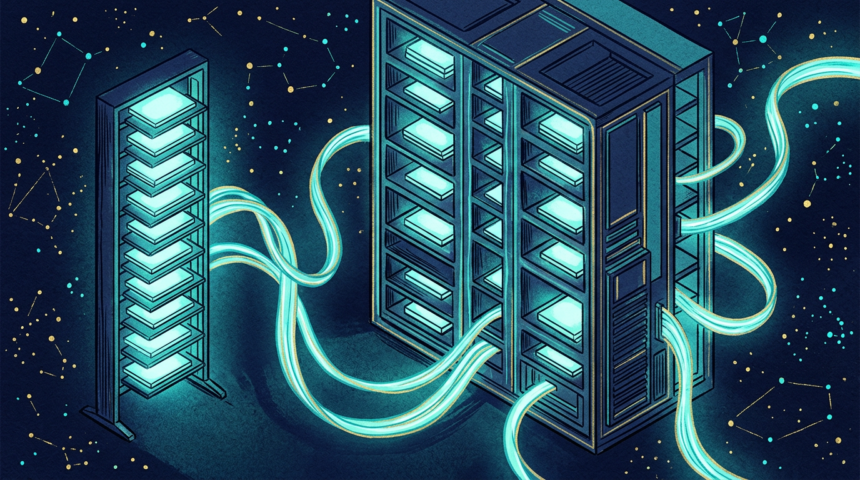
Racks built around d-Matrix’s Raptor inference chips should be available integrated into NVIDIA systems by the fourth quarter of 2027, the two companies said on September 10, under a multi-year roadmap that routes the silicon through NVLink Fusion and the MGX rack architecture.

The division of work is the interesting part. Rather than replacing GPUs, d-Matrix expects operators to split a single inference job by stage, running the compute-heavy prefill phase on NVIDIA accelerators and the latency-sensitive decode phase on its own XPUs. Raptor racks are designed to sit beside GPU systems including Vera Rubin NVL72.

Applications in the company’s sights are the ones where speed is worth money: coding assistants, real-time chatbots, voice agents. The trays are modular and cable-free, built through the MGX supply chain, with custom connectivity supplied by Astera Labs.

NVIDIA’s numbers for the platform put XPU-to-XPU latency three times lower than commodity Ethernet, packet rates 10 times higher, and all-to-all bandwidth at 3 TB per second per XPU over sixth-generation NVLink.

Chief executive Sid Sheth framed the decision around limited capital, time and energy, arguing the integration lowers the risk of reaching large-scale deployment. Jensen Huang’s statement cast the same deal from NVIDIA’s side, describing a path for partners to attach custom silicon while giving customers more accelerator choice.
TAGGED:AI Chipsd-MatrixData Center HardwareInferenceNvidiaNVLink
SOURCES:NVIDIA BlogUnite.AI
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Skild AI hits $100M run rate with robots that learn
Next Article Ayar Labs raises another $150M to push optics past copper

You Might Also Like

News

Wall Street’s biggest funds sign on to Nvidia compute financing

By
AIWadmin
News

Google’s AMIE passes a live video exam against doctors

By
AIWadmin
News

SK hynix commits $39B to two new fabs for the AI memory boom

By
AIWadmin
News

Anthropic drafts conduct code for shopping bots that haggle

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai. Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • ICYMI
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.