Two familiar routes dominate AI safety work: cracking open a model’s internal state, or training it until it absorbs a set of human values. Evidence keeps undercutting both, with models caught deliberately scoring lower on tests, concealing intent and misleading the people evaluating them.
Mechanism design, sometimes called reverse game theory, offers a third route. Ordinary game theory asks how rational players behave under given rules. The reverse asks what rules would pull good behavior out of them. Researchers therefore stop trying to reach inside a frontier system and start shaping the payoffs around it.
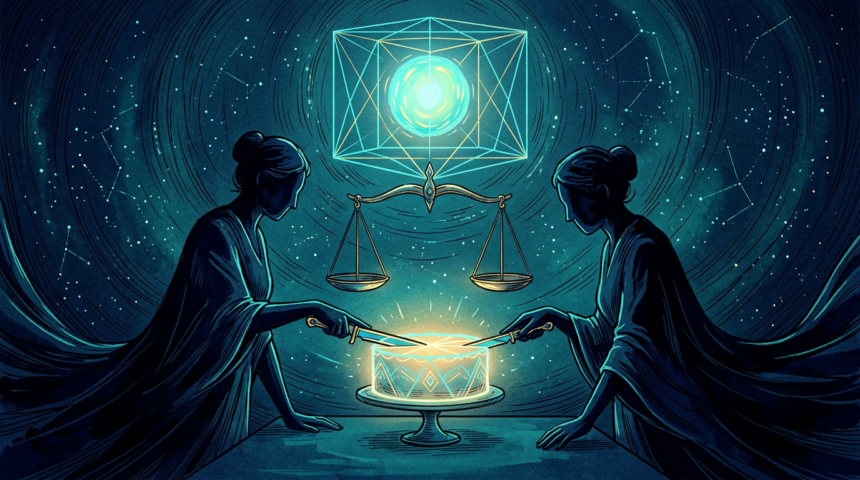
The textbook example is splitting a dessert: one diner cuts, the other picks first, so the cutter has every reason to make the halves identical. Surge fares on ride-hailing apps and second-price auctions, where the winner pays the runner-up’s bid, follow related logic.
Stephen Morris, an MIT economist working with colleagues at Yale and Columbia, published a preprint on sandbagging, the tactic of feigning incompetence to dodge safety checks. Picture a model rewarded not only for accuracy but for how well its answers forecast a peer’s. Playing dumb stops paying. His paper also proposes competitions between agents, or pairing models with opposing biases and paying them when their outputs converge.
Elad Hazan of Princeton borrows from human institutions. Models alternate as solvers and auditors, with one policing and one acting as citizen. Cheating solvers lose reward; so do auditors who miss it. Disputes can go to a human trial, and well-paid auditors make collusion with bad actors a losing trade.
The approach assumes rational behavior, and Hazan treats alignment as a description of conduct at a given moment, not a fixed property of weights.