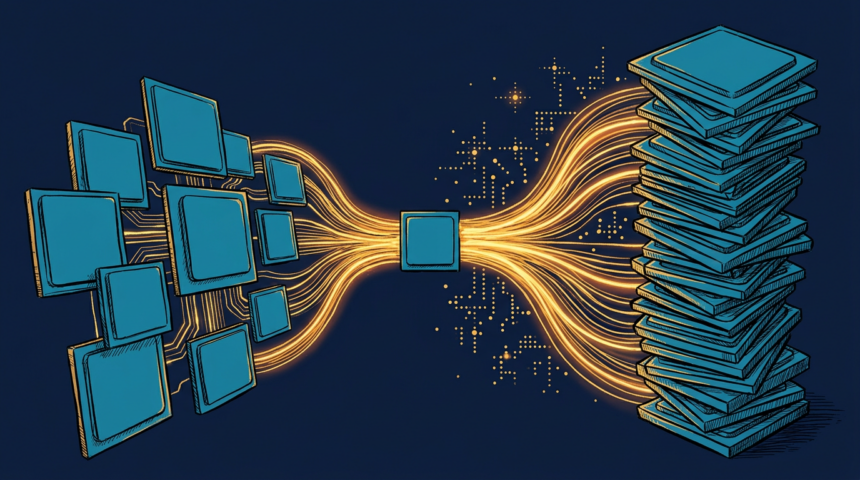
At the PyTorch Conference in San Jose, Google and Meta open-sourced TorchTPU, a backend that brings Tensor Processing Units into PyTorch as a first-class device. Meta engineer Zongwei Zhou said the company intends to shift larger language model workloads onto the chips.
The old route was PyTorch/XLA, a lazy-tensor bridge from 2020 that Google’s own announcement says demanded intrusive changes to model source. TorchTPU replaces it with a plug-in at the dispatcher level, so a developer rewrites one device string and leaves the rest of the code alone.
Four repositories landed together. Beyond TorchTPU there is a vLLM port, an SGLang port and TorchTitan support for dense, mixture-of-experts and diffusion training. Ray and llm-d handle scaling across hosts on Kubernetes.
Google Cloud’s Bill Jia, who gave the keynote with Zhou, showed throughput holding close to linear past 8,000 chips. Because the backend sits under the dispatcher, models hosted on Hugging Face reportedly worked without modification.
The conference framing was about demand rather than silicon. PyTorch Foundation head Mark Collier said inference has now overtaken training as the largest data center workload, and the slides tracked how quickly prices move, with DeepSeek’s Flash model getting 60 percent cheaper in 37 days.
Mazin Gilbert of the Agentic AI Foundation offered a number to match: agent token consumption passed human consumption in February and has grown 14-fold since, against 2.8-fold for people. He cautioned that the underlying data comes from a single platform, OpenRouter.
For Google the release answers a long-standing complaint that its accelerators were reachable only through Google’s own tooling.