Thursday, 29 Oct 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI’s Berlin pitch was about owning the runtime, not the model

    By
    AIWadmin

    A one-researcher model lab ships a 10M-token coding engine

    By
    AIWadmin

    Liquid AI branches six small models off one backbone

    By
    AIWadmin

    Google gives language models a sleep cycle to remember new facts

    By
    AIWadmin

    Harvey clears the federal security bar for legal AI

    By
    AIWadmin

    Musk predicts a cull of 200 neoclouds as debt markets close

    By
    AIWadmin
  • Articles

    Google hands Oracle the keys to sell its TPUs

    By
    AIWadmin

    Airbnb drags recommendation data from two days old to twenty seconds

    By
    AIWadmin

    Android Studio opens its doors to Claude, Codex and 40 other agents

    By
    AIWadmin

    A Delaware plan would let software run companies with nobody in charge

    By
    AIWadmin

    OpenAI halves its agent pricing with a cheaper vision model

    By
    AIWadmin

    Claude for Legal now checks its own citations first

    By
    AIWadmin
  • Spotlight

    Circuit Mind puts a swarm of agents on schematic review

    By
    AIWadmin

    Upwind turns down a takeover and raises more instead

    By
    AIWadmin

    DeepMind keeps Gemini 4 Carbon behind a cyber defenders gate

    By
    AIWadmin

    Nvidia folds three speech jobs into a single open model

    By
    AIWadmin

    An inference cloud bets on rival silicon while the bears circle

    By
    AIWadmin

    Publishing staff threw a party for an AI assistant that died

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

Nvidia frees the GPU scheduler it acquired back in 2024

The full orchestration stack ships under Apache 2.0, giving platform teams a self-hosted alternative to paid Nvidia subscriptions.

AIWadmin
Last updated: October 20, 2026 2:11 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

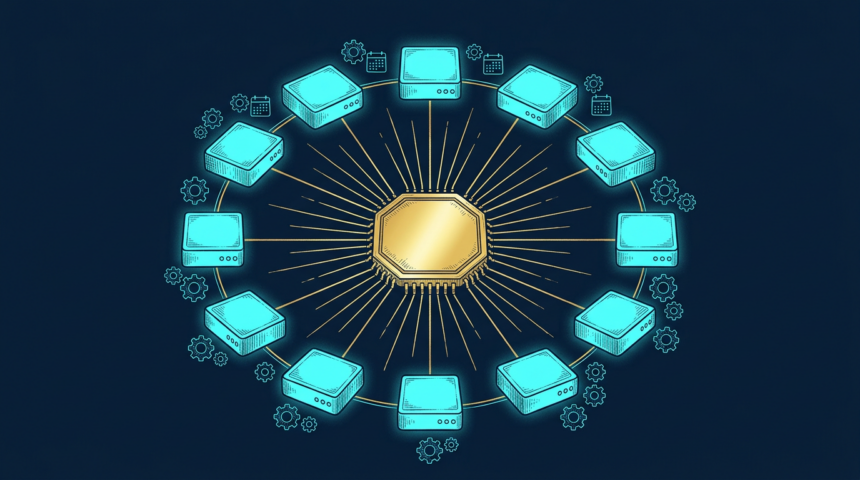
Nvidia has released its complete GPU orchestration platform as open source under Apache 2.0, publishing the code on GitHub through its DSX AI Factory organisation. The move hands production scheduling and quota management to anyone willing to run it.

The repository is a monorepo holding a control plane, cluster services, an installer, a command line tool and an MCP server for AI assistants. A local build compiles roughly 50 Go services from source.

Four pieces teams can adopt separately

KAI Scheduler is the Kubernetes-native engine, a CNCF Sandbox project covering gang scheduling, fair-share allocation and topology awareness. A GPU Fractioning Operator brings CUDA 13.4 native fractions with driver-enforced memory limits, replacing Nvidia’s older proprietary approach.

KAI Resource Management adds projects, departments and quotas, with worked examples guaranteeing half a cluster to one research team. Workload Map describes job types like PyTorchJob and RayCluster but does not schedule anything itself.

Development does not require a GPU. A single script builds into a five-node Kind cluster pinned to Kubernetes v1.32.5 and simulates eight Tesla-A10 cards, so a laptop on macOS or Linux can run the whole stack. Windows is not supported.

The community edition carries no Nvidia enterprise support, and AMD and Intel accelerators are out of scope. Nvidia also pointed to Model Streamer, which cut model load times three to six times on eight H100 virtual machines in a Microsoft benchmark.

The comparison that matters is scope. Volcano, Kueue and YuniKorn are all Apache 2.0 but focus on scheduling or queueing alone. This stack ships the management layer above the scheduler, which is the part enterprises usually pay for.
TAGGED:AI InfrastructuregpuGPU OrchestrationKubernetesNvidiaopen source
SOURCES:NVIDIA DeveloperGitHubMarkTechPost
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article MiniMax confirms its stealth model was a Flash release all along
Next Article Mistral’s 209M forecasting model tops charts without a GPU

You Might Also Like

News

Needle 2 squeezes tool calling into a 14MB model binary

By
AIWadmin
News

Dyna-2 robot model learns from 170 years of human video

By
AIWadmin
News

Replit drops credit costs with a free tier on GPT-5.6 Luna

By
AIWadmin
News

Wobbly Humanoid Robots Get Airport Trial, But Vague Videos Raise Doubts

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.