Thursday, 24 Sep 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI slots two cheaper GPT-6 models beneath Astra

    By
    AIWadmin

    Researcher hijacks Meta’s Muse agent through a hidden setting

    By
    AIWadmin

    ChatGPT learns to take voice orders for office chores

    By
    AIWadmin

    YouTube hands creators an AI agent for titles and thumbnails

    By
    AIWadmin

    Listeners can now rewrite the Spotify algorithm in plain words

    By
    AIWadmin

    Anthropic’s Claude agents flag a new enzyme family in viral DNA

    By
    AIWadmin
  • Articles

    Data shop Snorkel AI banks $350M as labs stockpile training sets

    By
    AIWadmin

    Ema banks $77M to push AI employees into the back office

    By
    AIWadmin

    US military command randomises routes to outfox enemy models

    By
    AIWadmin

    Kyutai teaches a speech model to do arithmetic out loud

    By
    AIWadmin

    Nokia hands developers a no-training route to calibrated answers

    By
    AIWadmin

    An open model sorts eight overlapping speakers in real time

    By
    AIWadmin
  • Spotlight

    DeepMind keeps cloud memory encrypted behind device-held keys

    By
    AIWadmin

    Anthropic trims Opus costs and speeds output in a mid-cycle refresh

    By
    AIWadmin

    Cisco Talos builds a fingerprint library for AI-driven malware

    By
    AIWadmin

    Google parks idle agents in a new open source runtime

    By
    AIWadmin

    OpenAI gives mathematicians a voice but hands them no brake

    By
    AIWadmin

    NVIDIA teaches its robotics stack to take instructions from agents

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
Articles

NVIDIA hands factory allocations to a planner built with Palantir

NVIDIA's operations team now uses a Palantir Foundry command center and its own cuOpt solver to decide weekly how parts move through its manufacturing network.

AIWadmin
Last updated: September 12, 2026 12:08 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
NVIDIA hands factory allocations to a planner built with Palantir
SHARE

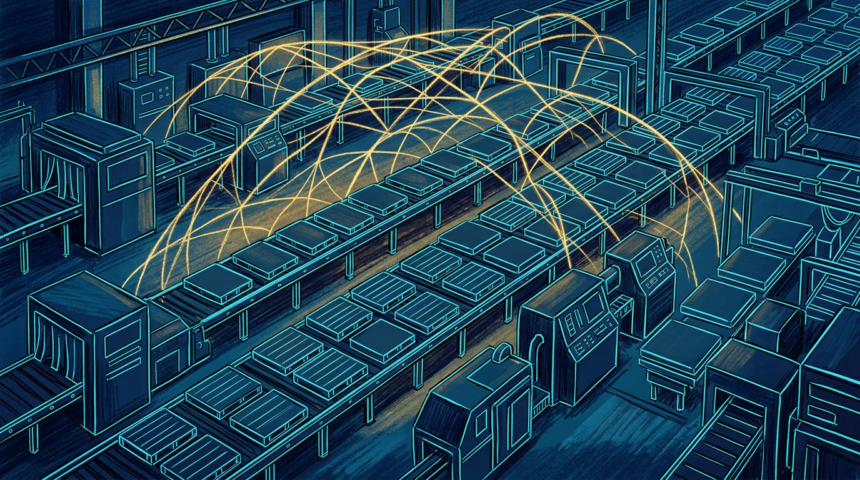
Weekly decisions about which factory receives which parts are now made with help from Palantir Foundry and cuOpt, the GPU-accelerated optimization library NVIDIA publishes as open source.

NVIDIA tracks delivery across two windows it calls time-to-rack and time-to-token, which together cover the stretch from wafer output to a working token. Hardware complexity has made that stretch harder to manage.

A single Grace Blackwell NVL72 rack holds 18 compute trays. Every tray calls for two Grace CPUs, four Blackwell GPUs and 32 HBM3e memory packages. Those parts come from thousands of suppliers, contract manufacturers and design partners, and the network behind the coming Vera Rubin generation will be twice as large.

Materials reach the line through three channels: direct inventory, consignment stock and outside suppliers. When one slips, assembly waits, and the delay shows up in a metric NVIDIA calls time of ownership. Planners rework the allocation weekly, looking two quarters out.

To coordinate all of it, the operations team built a Digital Supply Chain Intelligence command center on Foundry, whose ontology models facilities, supplier commitments, component stocks and production targets as linked objects. cuOpt reads that layer and formulates distribution as a mixed-integer linear program that minimizes time of ownership across every tier of the bill of materials.

Math alone could not capture what human planners watch — supplier calls, weather, partner emails, geopolitics — so NVIDIA post-trained Nemotron 3.5 Lightning, a 30B mixture-of-experts model with about 3B active parameters, after redacting sensitive fields from historical records. It reached 86.7 percent decision accuracy against 55.5 percent for the larger Nemotron 3 Ultra and 17.5 percent for the untuned base model. Fine-tuning ran on two B200 GPUs and finished in minutes, and planner overrides flow back into the ontology to build preference pairs for reinforcement learning.
TAGGED:cuOptManufacturingnemotronNvidiaPalantirSupply Chain
SOURCES:AI News
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Google's ToolGrad builds tool-use data by running the APIs first Google’s ToolGrad builds tool-use data by running the APIs first
Next Article T. Rowe Price puts Claude to work across its research desks T. Rowe Price puts Claude to work across its research desks

You Might Also Like

Articles

Pope Leo XIV urges ethical AI use to protect youth and uphold human dignity

By
Zoe Chang
News

NVIDIA teaches its robotics stack to take instructions from agents

By
AIWadmin
Articles

Stanford turns published papers into runnable research agents

By
AIWadmin
Articles

NVIDIA open-sources OSMO to run robot pipelines from one file

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.