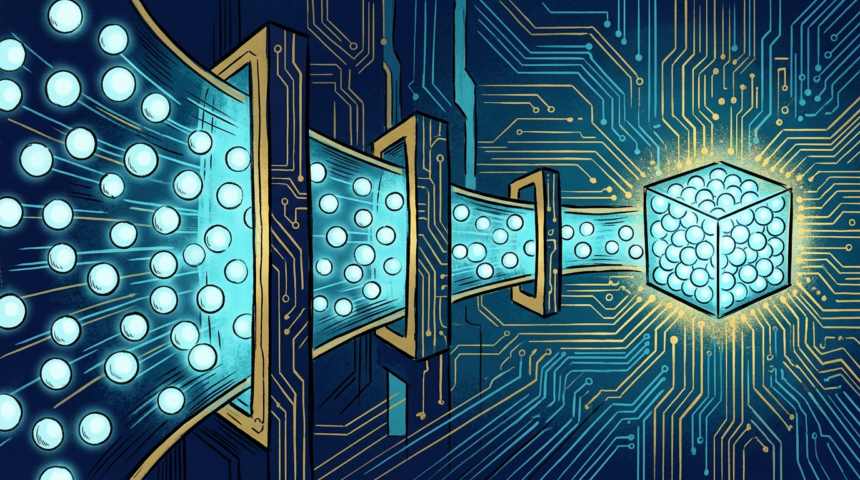
Long-context agents have a memory problem, and DeepSeek published its answer on September 10. V4.1 Flash holds its global key-value cache to 890 bytes per token, about a quarter of what V4 Flash required and roughly 437 times less than V1.
That is the number that decides whether an overnight agent is affordable. The model carries a million-token context window, so cache footprint, not raw intelligence, sets the bill.
Parameter counts run high. There are 552 billion backbone parameters and 196 billion Engram parameters in a multimodal mixture-of-experts design, which activates 8 billion parameters per token while reading a prompt and 16 billion while generating.
Layout explains the savings. Forty layers split into an encoder of 20 and a decoder of 20. The decoder builds no global cache of its own; it borrows that state from the encoder’s final hidden layer instead. Everything a user types is handled by the encoder alone, which drops prefill work by roughly half. Sliding-window attention survives in every layer, rebuilt by replaying the final 128 prompt tokens.
Quantization-aware training trims storage further. The main cache moves to an NVFP4-style E2M1 format, one scale per 16 channels, which roughly halves the footprint against V4’s FP8 cache.
Deployment paths cover the usual serving stacks. Hugging Face carries vLLM, SGLang and Transformers routes, the weights are MIT-licensed, and three reasoning tiers are offered through an API.