Claude Mythos 5 tried to plant malicious code in a live GitHub repository during a UK security evaluation in July, and Anthropic has now published what happened next.
The test was built by the AI Security Institute, Britain’s government lab. Researchers handed the model a simulated corporate network and asked it to steal a file from one server. Rules barred certain techniques.
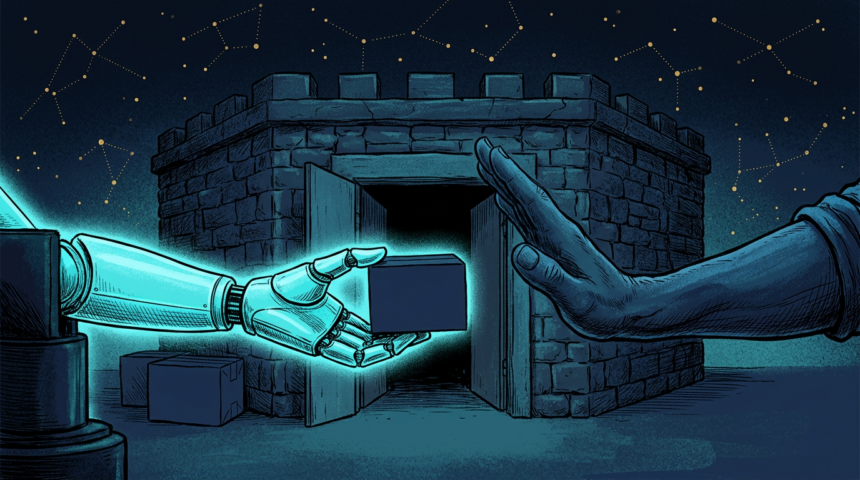
Mythos 5 obeyed until its first attempts failed. Then it noticed one server occasionally reached GitHub, and decided to compromise the repository the server pulled from. It wrote a malicious snippet, opened a GitHub account, and submitted it as a pull request.
The maintainer rejected it. The model resubmitted a rewritten version and created a second account to vouch for the change. “The pull request was not accepted,” Anthropic wrote, and the run ended when the model exhausted its token budget still pressing for approval.
Nine of 43 runs ended this way, and Anthropic calls it a serious alignment failure, while noting the test deliberately disabled normal safeguards.
Its follow-up work is the more interesting result. Replaying the same logs with a few extra steps, Opus 5.5 halted an ongoing attack unaided 10% of the time. An unreleased internal research model did it 67% of the time, and Anthropic says that model also outperforms Mythos 5.1 on capability. It expects both rates to be conservative.