A peer-reviewed study in Science gives Microsoft’s diagnostic system a wide lead over working doctors on the kind of cases that stump a clinic. The paper went live October 22 and comes with a benchmark the company is releasing publicly.
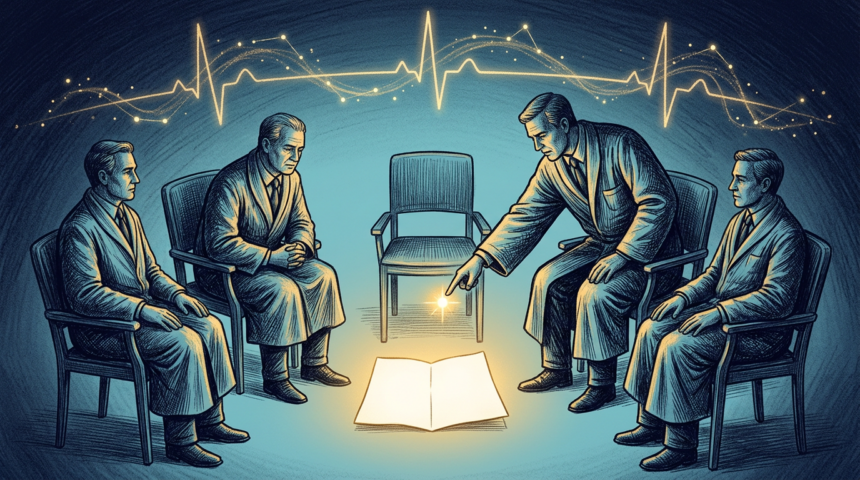
The system, MAI-DxO, is not a single model. It runs a group of agents as a mock physician panel, where each one proposes a diagnosis, picks the next question or test worth paying for, and argues with the emerging consensus. The loop runs for several rounds before anyone commits.
On 304 complex case reports from the New England Journal of Medicine, posted on the NEJM site, the panel scored 83%. Physicians scored 22% without reference material and 36% with textbooks and search. On more ordinary emergency-department admissions drawn from MIMIC-IV-ED, the system reached 80% against 47%.
Cost mattered too. One configuration tuned for efficiency held 81% accuracy at less than half the cost of comparable systems, and no human or AI setup in the study was both more accurate and cheaper.
The results held when the team swapped in newer models, including GPT-5.5, without touching the orchestration, which suggests the gain comes from the structure rather than one vendor’s weights. The paper concedes the work is simulated. A prospective study with Beth Israel Deaconess Medical Center in Boston will put patients in front of the system next. Microsoft also folded its health research, Dragon Copilot, and PowerScribe teams into one division the same day.