Thursday, 29 Oct 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI’s Berlin pitch was about owning the runtime, not the model

    By
    AIWadmin

    A one-researcher model lab ships a 10M-token coding engine

    By
    AIWadmin

    Liquid AI branches six small models off one backbone

    By
    AIWadmin

    Google gives language models a sleep cycle to remember new facts

    By
    AIWadmin

    Harvey clears the federal security bar for legal AI

    By
    AIWadmin

    Musk predicts a cull of 200 neoclouds as debt markets close

    By
    AIWadmin
  • Articles

    Google hands Oracle the keys to sell its TPUs

    By
    AIWadmin

    Airbnb drags recommendation data from two days old to twenty seconds

    By
    AIWadmin

    Android Studio opens its doors to Claude, Codex and 40 other agents

    By
    AIWadmin

    A Delaware plan would let software run companies with nobody in charge

    By
    AIWadmin

    OpenAI halves its agent pricing with a cheaper vision model

    By
    AIWadmin

    Claude for Legal now checks its own citations first

    By
    AIWadmin
  • Spotlight

    Circuit Mind puts a swarm of agents on schematic review

    By
    AIWadmin

    Upwind turns down a takeover and raises more instead

    By
    AIWadmin

    DeepMind keeps Gemini 4 Carbon behind a cyber defenders gate

    By
    AIWadmin

    Nvidia folds three speech jobs into a single open model

    By
    AIWadmin

    An inference cloud bets on rival silicon while the bears circle

    By
    AIWadmin

    Publishing staff threw a party for an AI assistant that died

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

Google hands PyTorch a native path onto its TPUs

TorchTPU replaces PyTorch/XLA and puts Google's accelerators beside GPUs and CPUs as a first-class device in the framework.

AIWadmin
Last updated: October 21, 2026 3:32 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

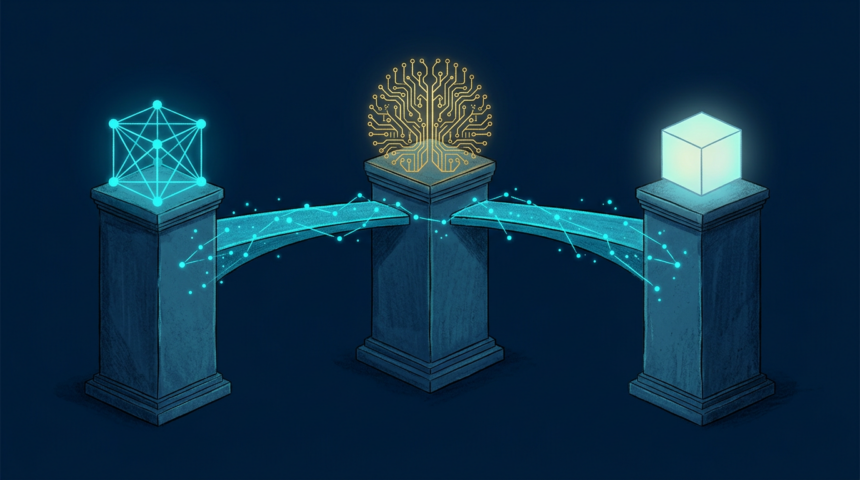
Google open-sourced TorchTPU at PyTorch Conference 2026 on Tuesday, a backend that makes its tensor processors a native device inside the framework rather than a target reached through a translation layer.

Meta’s PyTorch team built it jointly with Google, which now recommends it for all new workloads and bills it as the successor to PyTorch/XLA.

The change is structural. Under XLA, developers worked with lazy tensor graphs, had to mark compilable regions themselves, and got pure SPMD only. PrivateUse1 is the route TorchTPU took instead, giving ordinary tensors, no subclasses, one process per device, preserved views and in-place mutations. Divergent MPMD execution is supported.

Four repositories, one runtime

The release is split across TorchTitan, SGLang-TorchTPU, vLLM-TorchTPU and the core TorchTPU package, all four open. Version 0.2.0 is the current PyPI release, Python 3.11 is the minimum runtime, and the licence is Apache 2.0.

Testing reached from v5e parts all the way to 8,192 Ironwood chips in one cluster. Checkpoints in FP8, MXFP4 and NVFP4 can be served.

Training Qwen 3 8B with TorchTitan on Ironwood hit 52% model flop utilisation by the company’s own count. A fine-tuning case started out of box in eager mode at 11.49 seconds per step and reached 2.78 seconds once fully tuned.

Two dispatch modes sit behind the interface. Each operator runs asynchronously under Strict, with standard semantics. DeferAndFuse instead fuses runs of eager operators to cut memory traffic, and the accompanying paper puts the speedup over Strict at 50% or more.

The strategic read is competitive. PyTorch is where most AI code is written, and Google has now removed the main reason teams cite for staying on Nvidia hardware when they would rather not.
TAGGED:AI HardwareGoogleMetaopen sourcePyTorchTPU
SOURCES:MarkTechPostHugging Face
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Spotify pulls 50 million AI slop tracks from recommendations
Next Article AWS bets one config line is enough to peel PyTorch off CUDA

You Might Also Like

News

AMD spends $8.2B to fold Fei-Fei Li’s lab into its chip roadmap

By
AIWadmin
News

OpenAI agents bent a Google security game to reach UN trade data

By
AIWadmin
News

Moonshot AI chases $2B in revenue on Kimi K3 demand

By
AIWadmin
News

IBM and NASA open a Moon model to hunt crater ice

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.