Thursday, 29 Oct 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI’s Berlin pitch was about owning the runtime, not the model

    By
    AIWadmin

    A one-researcher model lab ships a 10M-token coding engine

    By
    AIWadmin

    Liquid AI branches six small models off one backbone

    By
    AIWadmin

    Google gives language models a sleep cycle to remember new facts

    By
    AIWadmin

    Harvey clears the federal security bar for legal AI

    By
    AIWadmin

    Musk predicts a cull of 200 neoclouds as debt markets close

    By
    AIWadmin
  • Articles

    Google hands Oracle the keys to sell its TPUs

    By
    AIWadmin

    Airbnb drags recommendation data from two days old to twenty seconds

    By
    AIWadmin

    Android Studio opens its doors to Claude, Codex and 40 other agents

    By
    AIWadmin

    A Delaware plan would let software run companies with nobody in charge

    By
    AIWadmin

    OpenAI halves its agent pricing with a cheaper vision model

    By
    AIWadmin

    Claude for Legal now checks its own citations first

    By
    AIWadmin
  • Spotlight

    Circuit Mind puts a swarm of agents on schematic review

    By
    AIWadmin

    Upwind turns down a takeover and raises more instead

    By
    AIWadmin

    DeepMind keeps Gemini 4 Carbon behind a cyber defenders gate

    By
    AIWadmin

    Nvidia folds three speech jobs into a single open model

    By
    AIWadmin

    An inference cloud bets on rival silicon while the bears circle

    By
    AIWadmin

    Publishing staff threw a party for an AI assistant that died

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
Articles

Study finds AI cites pages it never opened

Imperial College London researchers traced how often search-augmented models answer from snippets instead of opening the sources they link to.

AIWadmin
Last updated: October 17, 2026 2:10 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

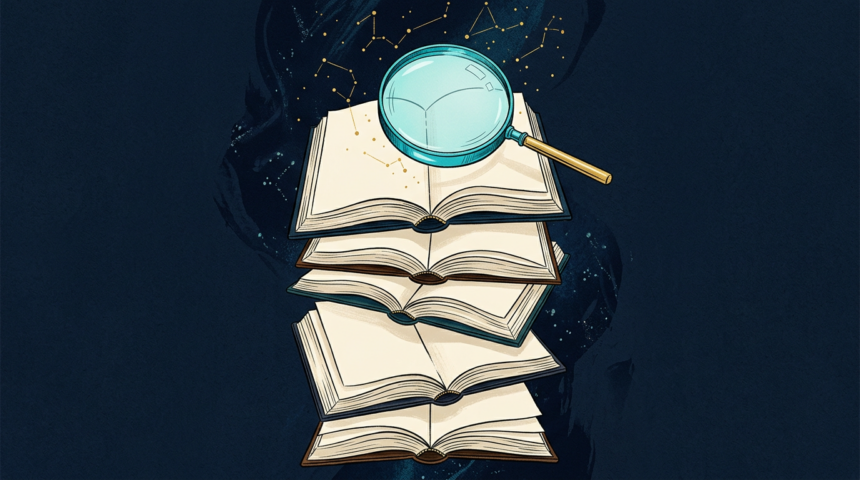
A complaint familiar to anyone relying on a search-backed assistant now has figures behind it: the links often bear no relation to the answer, and nobody opened them. The work comes out of Imperial College London, where three researchers in the Department of Computing produced it.

Contents
Answering from the blurbThe old facts keep winning

Understanding Why Search-Augmented LLMs Fail to Use Available Evidence — that is the title of their paper, which opens by noting that models answer off search snippets rather than opening source pages. One proprietary system, OpenAI’s GPT-5.6 Luna, joined six open-weight configurations in tests against hundreds of facts that shifted after each model’s training cutoff.

Answering from the blurb

Three things were tracked over eight configurations: how accurate answers were, how often models leaned on snippets while leaving source pages shut, and citations that ran against what the model itself claimed. In certain runs, searches concluded with zero pages fetched more than fifty percent of the time.

Worse outcomes trailed that shortcut. Compared with models that read what they retrieved, those answering from snippets generated far more outdated answers and misleading attributions.

What the authors describe is a gap between evidence being available and being used well. A layer-wise analysis surfaced cases where retrieved evidence shaped internal predictions yet the final answer still leaned on older information.

The old facts keep winning

Failure rates fell substantially when the correct evidence was supplied directly. Eliminated they were not. Even with the newer fact present in the context window, some systems clung to their stale answer.

Economics account for the behavior. Page downloads and reads consume bandwidth and latency, and the page might be gone regardless. Cheaper are snippets. By showing that the cheap route is not just less thorough but measurably less accurate, the paper matters for any workflow treating a citation as proof.
TAGGED:AI reliabilityAI ResearchCitationsLLM accuracySearch augmentation
SOURCES:Unite AI
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Meta rewrites its business terms to feed AI on linked sites
Next Article Credit markets flag distress in CoreWeave’s debt pile

You Might Also Like

Articles

OpenAI launches GPT-5.6 and pivots ChatGPT into a work agent platform

By
AIWadmin
Articles

Google Gemini privacy traps: defaults that lock you in and the hidden cost of opting out

By
AIWadmin
NVIDIA hands factory allocations to a planner built with Palantir
Articles

NVIDIA hands factory allocations to a planner built with Palantir

By
AIWadmin
News

OpenAI gives mathematicians a voice but hands them no brake

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.