Exa’s newest research setting is built for questions that have no natural stopping point.
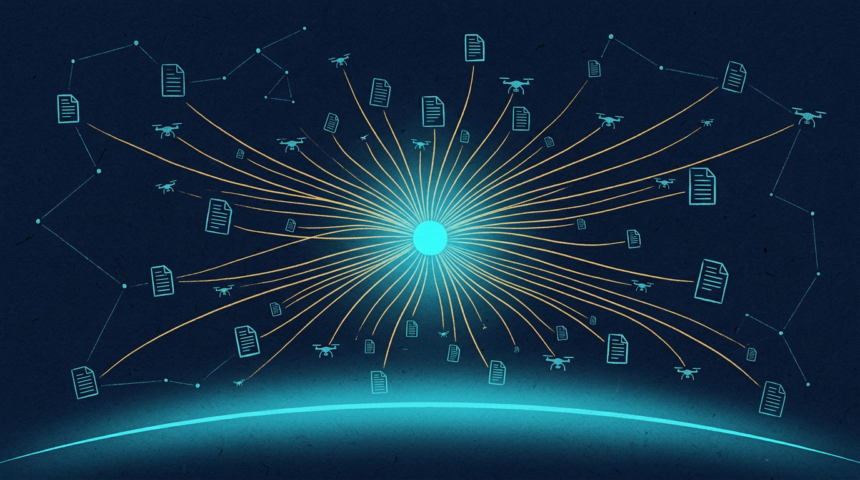
The search startup calls it Agent Ultra, the top effort tier on its Agent API. Tasks get split into subtasks, subagents fan out across several domains at once, and the system routes frontier models to the hard steps while cheaper models handle the rest. A typical complex run takes about 30 minutes, and the hardest can grind for three hours.
The advertised use cases are large list building, entity enrichment and questions that need thousands of sources. Ultra can also extend an existing list, excluding rows a customer already has from new results.
Exa published benchmark results against Perplexity’s WANDR suite, a set of 500 wide-and-deep data collection tasks, Google DeepMind’s 900-prompt DeepSearchQA, and its own WideSearch and Company Find-All tests. On WANDR, Exa reports a 9.1-point absolute gap over Claude Opus 5.5. The company ran some competitors itself where vendors had not published figures, and describes the numbers as vendor-reported and not yet independently reproduced.
Ultra runs through the existing Agent run endpoint by setting the effort field to ultra, and is also exposed as an OpenAI-compatible reasoning effort. Runs default to a $20 ceiling, with budgets allowed between $1 and $100 and durations from five minutes to three hours. It is a hosted API only, with no open weights to self-host.