Sunday, 8 Nov 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    Google takes over a troubled Wyoming campus and tees up 17 billion

    By
    AIWadmin

    Eight hundred hacking agents sat open and nobody noticed

    By
    AIWadmin

    An unreleased Claude build closed a proof that stumped theorists since 2008

    By
    AIWadmin

    Agility Robotics reaches Nasdaq without a shipping product

    By
    AIWadmin

    Claude now reads your statements and keeps its hands off the money

    By
    AIWadmin

    Google stretches Gemini video to 15 seconds and cuts the rate

    By
    AIWadmin
  • Articles

    Meta lets Muse agents build their own little rooms

    By
    AIWadmin

    Physicl raises 10 million to make simulation honest enough for robots

    By
    AIWadmin

    Texans turned the data center boom into a ballot question

    By
    AIWadmin

    Clutch sits at 50 times revenue in a reported Palo Alto deal

    By
    AIWadmin

    Ramp’s card data says the AI spending boom has plateaued

    By
    AIWadmin

    Inkling 2 Small jumps to 31 on intelligence index for Thinking Machines

    By
    AIWadmin
  • Spotlight

    Underdog shrinks a voice engine to 32MB inside a browser game

    By
    AIWadmin

    Together lets coding agents rewrite the forward pass all day

    By
    AIWadmin

    Half a million H200 chips wait out a decision in Hong Kong

    By
    AIWadmin

    OpenAI’s bug hunt turns up 948 paths to root

    By
    AIWadmin

    Baidu hands out a 280B model with no instructions attached

    By
    AIWadmin

    Claude cites a wire service after a quiet licensing turn

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

Perplexity reuses LLM kernels to keep embedding serving cheap

Engineers at Perplexity detail a GPU stack where batch and online embedding workloads borrow prefill and decode paths.

AIWadmin
Last updated: September 6, 2026 8:59 pm
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

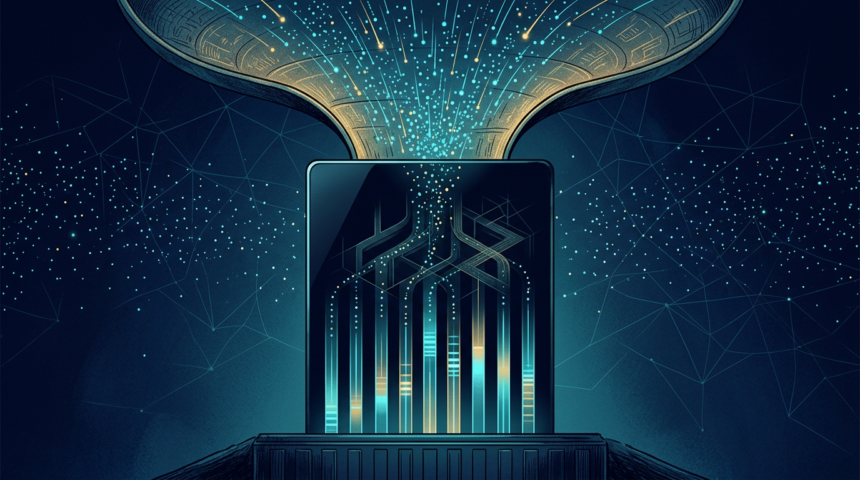
Search and answer products pay a quiet tax on every query: text has to become vectors before retrieval can start. Perplexity, which runs embedding and ranking models across its search engine, its agent computer, and its API platform, just published the serving playbook behind that step in a post from its engineering team.

The unorthodox call at the center is reuse. Embedding models are small enough that their workloads resemble familiar phases of LLM generation: rebuilding or refreshing an index behaves like prefill, the compute-heavy stage, while embedding a short live query behaves like decode, which is memory-bound. Rather than stand up a dedicated embedding engine, Perplexity runs both kinds of work on the kernels its main LLM stack already uses.

Scheduling leans on a component called Tulip that admits sequences in arrival order. The team argues that simple policy is correct at the sizes it serves, since the linear cost of dense layers, not attention’s quadratic term, dominates for short embedding sequences, making latency scale with tokens rather than the number of concurrent requests. Saturation arrives around 512 tokens on a sub-billion-parameter model, after which extra sequences stop improving efficiency. Small batches also risk spending more time launching kernels than executing them, so the stack captures whole-model CUDA graphs, folding every launch into a single driver call. Perplexity says it pushed changes upstream to FlashInfer so those graphs can be captured, and graphs are rebuilt per configuration bucket.

A Rust request path and an asynchronous result tracker round out the architecture. The write-up extends a string of infrastructure deep dives from Perplexity covering Blackwell hosting and tokenizer tuning, published as AI search and agent products everywhere compete to shrink the cost of retrieval at scale.
TAGGED:AI InfrastructureembeddingsGPU inferencePerplexityretrievalvector search
SOURCES:MarkTechPostPerplexity Blog
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Lyria 3.5 lets Gemini users compose full songs from prompts
Next Article Roland’s Melody Flip hands producers AI seeds, not finished songs

You Might Also Like

News

Restate banks $20M as agents make durable code valuable

By
AIWadmin
News

Musk’s Threats and Failed Power Grab Expose OpenAI’s Chaotic Founding

By
AIWadmin
News

Abbott glucose streams feed Gemini health coaching at Google

By
AIWadmin
News

Apple weighs pay-per-use deals to feed Siri the news

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai. Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • ICYMI
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.