Google Cloud AI Research starts from an assumption most self-improvement work rejects: the weights stay frozen, and only the scaffolding around them gets retuned.
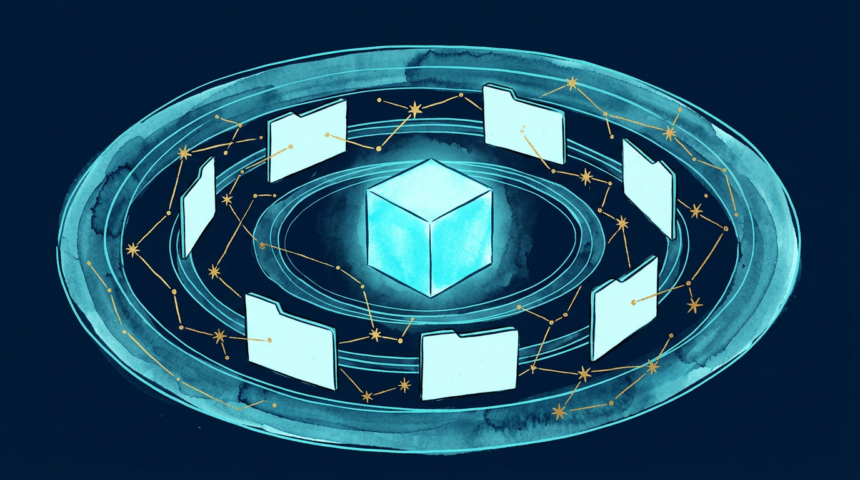
The result is Harness squared, written Harness2, version 0.1.0. Prompts, tool definitions, memory, skills and orchestration form the scaffold, presented as eight editable components, each one a file mounted on disk.
It needs Linux plus Python 3.12 or 3.13 and reaches models through Vertex AI. No training happens anywhere in the loop. The authors argue an agent can improve measurably while the underlying model stays exactly as shipped.
Open-world deployments are the target setting: tasks arrive unseen and no verifier can confirm the answer. Labeled data and test cases, which the authors say most self-improvement methods quietly rely on, are precisely what such settings lack.
Two recursion levels do the work. Inside a single task, an editor submits two candidate harnesses, one addressing general weaknesses such as planning or tool use and the other tuned to the domain. Both are run on that task, and a composer retains only the edits that the observed behavior justifies. Once a task ends, a reflector files the adopted harness alongside a lesson library that informs the next proposal, while the base configuration remains the starting point for every new task.
Testing covered WorkBuddy-Bench, JobBench and Harvey’s LAB, run with Gemini 3.5 Flash and GLM-5 as executors on OpenCode and Codex. All four executor-benchmark pairings improved on all three benchmarks after a single refinement step. The largest gain came from GLM-5 on OpenCode against WorkBuddy-Bench, which climbed from 64.2 to 75.7.
What makes the result notable is where the gains land: weaker executors benefit most. Capability the model already possessed, but which the surrounding code never surfaced, appears to be recovered by the framework itself.