Thursday, 29 Oct 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI’s Berlin pitch was about owning the runtime, not the model

    By
    AIWadmin

    A one-researcher model lab ships a 10M-token coding engine

    By
    AIWadmin

    Liquid AI branches six small models off one backbone

    By
    AIWadmin

    Google gives language models a sleep cycle to remember new facts

    By
    AIWadmin

    Harvey clears the federal security bar for legal AI

    By
    AIWadmin

    Musk predicts a cull of 200 neoclouds as debt markets close

    By
    AIWadmin
  • Articles

    Google hands Oracle the keys to sell its TPUs

    By
    AIWadmin

    Airbnb drags recommendation data from two days old to twenty seconds

    By
    AIWadmin

    Android Studio opens its doors to Claude, Codex and 40 other agents

    By
    AIWadmin

    A Delaware plan would let software run companies with nobody in charge

    By
    AIWadmin

    OpenAI halves its agent pricing with a cheaper vision model

    By
    AIWadmin

    Claude for Legal now checks its own citations first

    By
    AIWadmin
  • Spotlight

    Circuit Mind puts a swarm of agents on schematic review

    By
    AIWadmin

    Upwind turns down a takeover and raises more instead

    By
    AIWadmin

    DeepMind keeps Gemini 4 Carbon behind a cyber defenders gate

    By
    AIWadmin

    Nvidia folds three speech jobs into a single open model

    By
    AIWadmin

    An inference cloud bets on rival silicon while the bears circle

    By
    AIWadmin

    Publishing staff threw a party for an AI assistant that died

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

Cerebras says splitting inference in two yields five times the throughput

By running prompt processing and token generation on separate hardware pools, Cerebras says it served five times more traffic without slowing output.

AIWadmin
Last updated: October 4, 2026 6:53 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

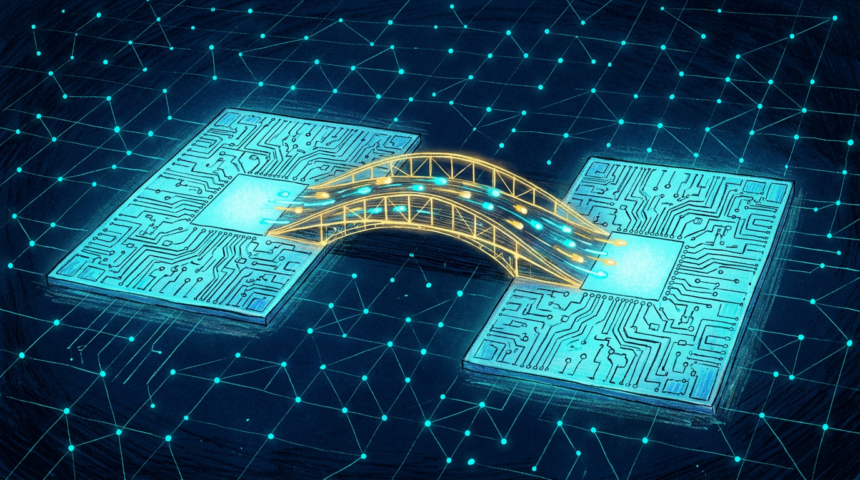
Inference has a scheduling problem that adding chips does not fix. Cerebras Systems says it can get more work from the same silicon by splitting a request’s two phases across separate hardware pools, a pattern it calls disaggregation.

The two phases behave differently. Prefill chews through an entire prompt as one large matrix operation. Decode then emits tokens one at a time, reusing a cache of earlier computations. Put them on the same chip and the compute-heavy half can stall requests that are already streaming.

Separate the pools and operators can size, batch and schedule each half for its own goal, whether that is a fast first token or smooth streaming. The cost is a handoff. The cache built during prefill has to move to the decode pool before generation can continue.

Cerebras put the throughput gain at 5x in early tests with the same wafer footprint, and credits its on-chip SRAM. The company lists 21,000 TB/s of memory bandwidth per WSE-3 wafer, against 22 to 23 TB/s for HBM4 GPUs, though it cautions the figures describe different memory tiers rather than measured token speeds.

On GPT-oss-120B, Artificial Analysis data from September 10 puts Cerebras at 1,669 output tokens per second, ahead of SambaNova at 708 and Groq at 475. The company says it is now pursuing heterogeneous disaggregation, pairing partner accelerators for prefill with its own chips for decode.
TAGGED:AI InferenceCerebrasData CentersPerformanceSemiconductorsWafer-scale
SOURCES:Unite.AI
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Anthropic pledges $100M to train 10,000 enterprise Claude engineers
Next Article PaleBlueDot AI banks $200M to expand its GPU cloud for frontier labs

You Might Also Like

News

OpenAI splits off a legal edition of its Astra model

By
AIWadmin
News

The Great AGI Rebrand: How Tech Titans Are Selling The Same Snake Oil Under New Acronyms

By
AIWadmin
News

Anthropic’s Claude agents flag a new enzyme family in viral DNA

By
AIWadmin
News

AI agent builder Yellow.ai lists on Nasdaq through $550M SPAC deal

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.