Security teams have a residency problem. Sending source code, architecture diagrams and unpatched findings to a closed frontier model means shipping them off the network, which banks bound by data-residency rules and air-gapped industrial sites cannot do. Aikido Security’s answer is Altar-1, an open-weight model published on Hugging Face, built by compressing Z.AI’s GLM-5.3 down to something one server rack can hold.
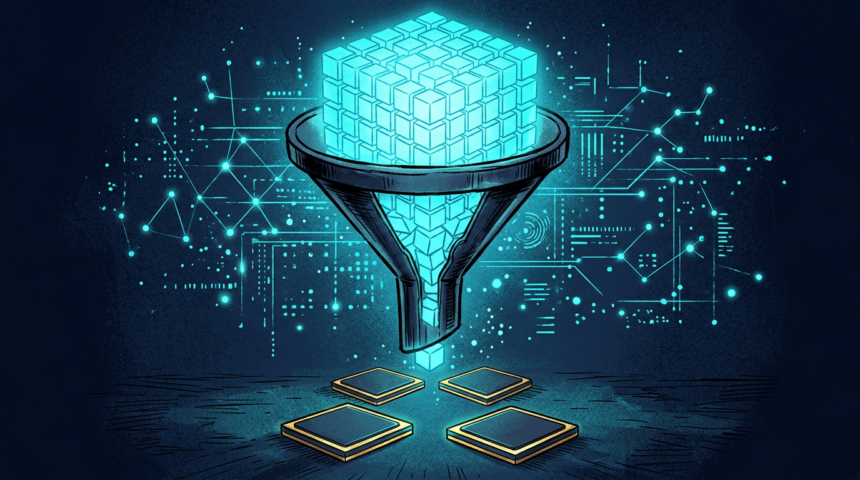
Compression is the hard part. Mixture-of-experts models keep every expert in memory even when a workload touches a few, and long agent contexts compete with weights for the same GPUs. GLM-5.3, a 753B-parameter model, sends each token to 8 of its 256 specialists, leaving roughly 40B active at any moment.
For calibration, Aikido fed the pruning pass with output from its own pentesting harness, then mixed in reasoning, multilingual material, coding and tool-calling. No customer data was used. The expert pool fell to 168 while routing stayed the same. The published build is 78.2 percent smaller than BF16 and runs on four NVIDIA H200 GPUs at 328GB, leaving room for a 128k-context cache.
Fidelity held up reasonably on the vendor’s own tests. Against Aikido’s internal CVE benchmark, 32 vulnerabilities across 30 repositories, Altar-1 kept 92 percent of its parent’s coverage with recall 5.2 points lower. Aikido also reports one critical-severity find during a client engagement, a single result it reported itself.