Dreaming up an experiment costs nothing; running one burns GPU hours that can stretch into days. That gap is why automated research agents stall, and it is the problem a system from Meta’s FAIR lab, Oxford and University College London attacks by ranking ideas before they touch hardware.
That choice is the target of a new system from Meta’s FAIR lab working with researchers at Oxford and University College London. They call the mechanism a research preference model, and it does one job: look at a batch of unexecuted experiment ideas, rank them, and hand the winner to the compute budget.
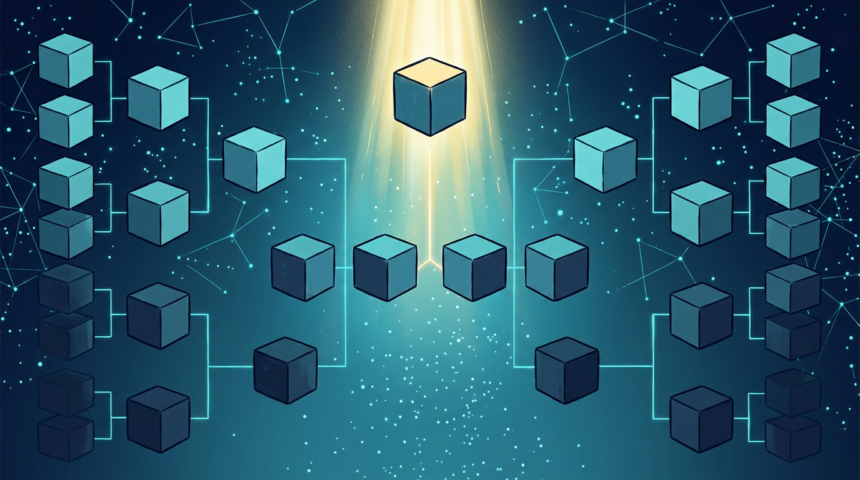
The designers deliberately avoided predicting absolute scores. Language models turned out to be unreliable at forecasting metrics or outcomes, so the RPM compares candidates against each other instead. When a parent idea spawns children, the scaffold generates 15 variants in parallel and runs them through a pairwise knockout, then executes only the survivor.
Under the hood the models stay frozen, so no fine-tuning is required. The scaffold, AIRA-dojo, and the evaluation benchmark, AIRS-Bench, are open source, and the backbone is the open-weights Qwen3.6-27B.
The bottleneck this addresses has sharpened as agentic research tools multiply. Idea generation has become nearly free, but verification still costs real silicon, and a ranker that concentrates spend on promising directions effectively multiplies what a fixed GPU budget can explore.