Thursday, 29 Oct 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI’s Berlin pitch was about owning the runtime, not the model

    By
    AIWadmin

    A one-researcher model lab ships a 10M-token coding engine

    By
    AIWadmin

    Liquid AI branches six small models off one backbone

    By
    AIWadmin

    Google gives language models a sleep cycle to remember new facts

    By
    AIWadmin

    Harvey clears the federal security bar for legal AI

    By
    AIWadmin

    Musk predicts a cull of 200 neoclouds as debt markets close

    By
    AIWadmin
  • Articles

    Google hands Oracle the keys to sell its TPUs

    By
    AIWadmin

    Airbnb drags recommendation data from two days old to twenty seconds

    By
    AIWadmin

    Android Studio opens its doors to Claude, Codex and 40 other agents

    By
    AIWadmin

    A Delaware plan would let software run companies with nobody in charge

    By
    AIWadmin

    OpenAI halves its agent pricing with a cheaper vision model

    By
    AIWadmin

    Claude for Legal now checks its own citations first

    By
    AIWadmin
  • Spotlight

    Circuit Mind puts a swarm of agents on schematic review

    By
    AIWadmin

    Upwind turns down a takeover and raises more instead

    By
    AIWadmin

    DeepMind keeps Gemini 4 Carbon behind a cyber defenders gate

    By
    AIWadmin

    Nvidia folds three speech jobs into a single open model

    By
    AIWadmin

    An inference cloud bets on rival silicon while the bears circle

    By
    AIWadmin

    Publishing staff threw a party for an AI assistant that died

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
News

Volantis lands $88M to break AI’s memory wall with light

Volantis closed an $88M Series A to commercialize a photonic inference system it says sidesteps the memory wall holding back large models.

AIWadmin
Last updated: October 2, 2026 2:33 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

Most AI silicon asks buyers to pick a side. Fast on-chip SRAM holds too little to fit a large model or a long context window, while the bigger HBM pools that solve capacity serve data more slowly. Volantis, a San Francisco semiconductor company, says four years of work produced hardware that sidesteps that tradeoff, and on October 1 it closed an $88M Series A to carry the design to market.

Lachy Groom and Abstract Ventures co-led the round. VXI Capital, Triatomic and Susa Ventures joined, along with angels Dwarkesh Patel, Naveen Rao and Sholto Douglas. Sam Altman, Jeff Dean and Dylan Patel are among the earlier backers, and the company puts total funding at $97M.

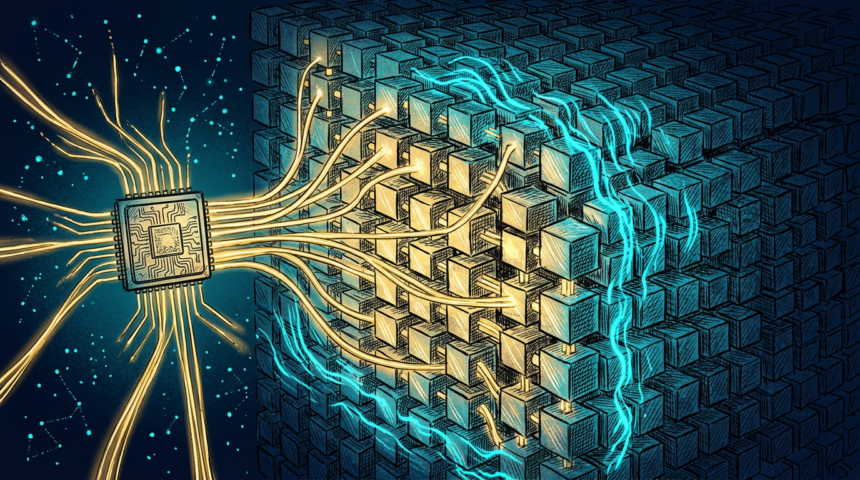
The centerpiece is the A-1 system, which pairs a photonic interconnect with off-chip memory. Where optics usually link one chip to the next, Volantis turns them on memory instead. Many memory dies are gathered into a single fabric, so each addition of capacity also adds bandwidth. Volantis is aiming at models beyond 20 trillion parameters, with as much as 10,000 tokens per second for every user, 10 TB of capacity and 240 TB/s of bandwidth; the rack unit draws 20kW and stands 15U tall. The company also claims 15 times better tokens per dollar than Nvidia’s Rubin on some low-latency workloads.

Chief executive Tapa Ghosh argues that speed has become a business metric for agents, since a coding agent that finishes in two minutes rather than 30 lets developers iterate far more often. Systems will not ship immediately, though: Volantis expects its first integrated inference engines to reach customers at some point in 2027, with more architecture details to come as the product nears commercialization.
TAGGED:AI ChipsAI InferencePhotonic ComputingSemiconductorsSeries AVolantis
SOURCES:Unite AI
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Ai2 opens a training stack built for trillion-parameter MoEs
Next Article Reddit cuts RSS and public API access to fight AI scraping

You Might Also Like

News

Lightspeed backs India’s AI founders with a $250M vehicle

By
AIWadmin
News

Eka Robotics reaches $1.45B on a gripper that learns by touch

By
AIWadmin
News

California builds its own AI defenses as federal funds fade

By
AIWadmin
News

Meta hands builders the firmware to wire Muse into any gadget

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.