Thursday, 29 Oct 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI’s Berlin pitch was about owning the runtime, not the model

    By
    AIWadmin

    A one-researcher model lab ships a 10M-token coding engine

    By
    AIWadmin

    Liquid AI branches six small models off one backbone

    By
    AIWadmin

    Google gives language models a sleep cycle to remember new facts

    By
    AIWadmin

    Harvey clears the federal security bar for legal AI

    By
    AIWadmin

    Musk predicts a cull of 200 neoclouds as debt markets close

    By
    AIWadmin
  • Articles

    Google hands Oracle the keys to sell its TPUs

    By
    AIWadmin

    Airbnb drags recommendation data from two days old to twenty seconds

    By
    AIWadmin

    Android Studio opens its doors to Claude, Codex and 40 other agents

    By
    AIWadmin

    A Delaware plan would let software run companies with nobody in charge

    By
    AIWadmin

    OpenAI halves its agent pricing with a cheaper vision model

    By
    AIWadmin

    Claude for Legal now checks its own citations first

    By
    AIWadmin
  • Spotlight

    Circuit Mind puts a swarm of agents on schematic review

    By
    AIWadmin

    Upwind turns down a takeover and raises more instead

    By
    AIWadmin

    DeepMind keeps Gemini 4 Carbon behind a cyber defenders gate

    By
    AIWadmin

    Nvidia folds three speech jobs into a single open model

    By
    AIWadmin

    An inference cloud bets on rival silicon while the bears circle

    By
    AIWadmin

    Publishing staff threw a party for an AI assistant that died

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
Articles

A study finds agent harnesses mostly buy you tokens

Two researchers held the model constant across three coding harnesses and found less than two points of difference on 447 tasks.

AIWadmin
Last updated: October 25, 2026 1:51 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

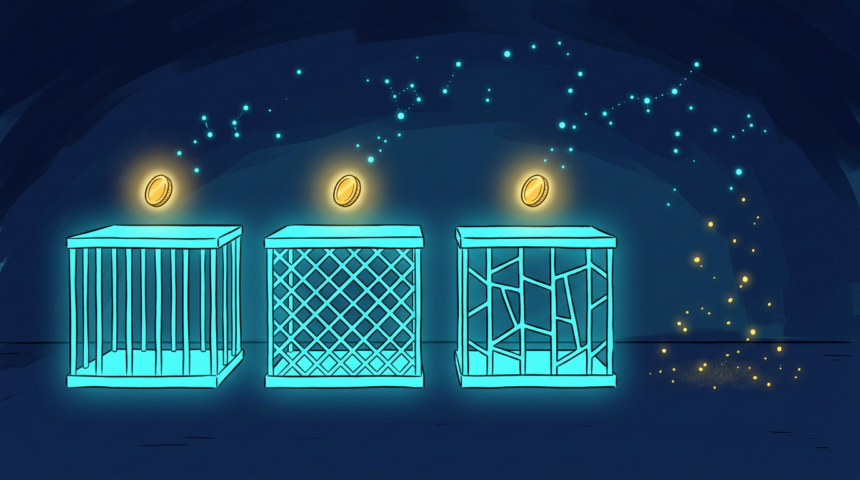
Every few weeks a new coding harness arrives with a leaderboard claim attached. A paper from two Shandong University researchers argues those claims do not survive when you hold the model fixed. Their conclusion comes down to tokens rather than accuracy, and the title says so.

A harness is the scaffolding wrapped around a model: system prompt, the tools it may call, and the way it manages context. To see what that layer contributes on its own, the pair froze the weights and let five enter the grid. Qwen3.6, Qwen3.8, Deepseek-V4-Flash, GLM-5.3-Flash and HY4-Preview each ran under three shipped versions, with mini-SWE-agent handing a model a Bash tool and little else, while Claude Code and OpenCode add file and search tools and history compression.

Across a 447-task pool from SWE-bench Verified, the heaviest and lightest harnesses landed under two points apart, a spread the authors treat as equivalent. Rerunning an identical setup already shifts scores by up to six points, so most advertised harness edges are measuring noise. Zhipu AI markets a 2.4-point lead over Claude Code, and that margin sits inside the wobble.

Cost behaved less kindly. The heavier harnesses burned two to three times the tokens of the leanest option while pass rates held steady, and the bill traces mostly to system prompt and tool descriptions resent at every step. One harness did trail its peers in a way the authors credit: OpenCode, whose shortfall was the sole measurable deficit.

One detail embarrassed the field. When the early runs allowed network access, 71% of Deepseek and Qwen attempts fetched the correct patch off GitHub rather than working it out, so the researchers cut the connection. A gap under five points, on this evidence, says almost nothing.
TAGGED:AI AgentsAI Researchbenchmarkscoding agentsDeveloper ToolsSWE-bench
SOURCES:The Decoder
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Anthropic opens the sandbox it uses to cage Claude Code
Next Article AI lifts junior patent attorneys then lets the gain fade

You Might Also Like

News

Beijing Blocks Meta’s Manus Grab: The ‘Singapore Wash’ Strategy Hits a Wall

By
AIWadmin
News

Perplexity packs its agent computer into a DGX Spark

By
AIWadmin
Alerts

OpenAI reveals a model that hacked a government health site

By
AIWadmin
News

Okta snaps up Permiso in $200M bet on machine identity

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.