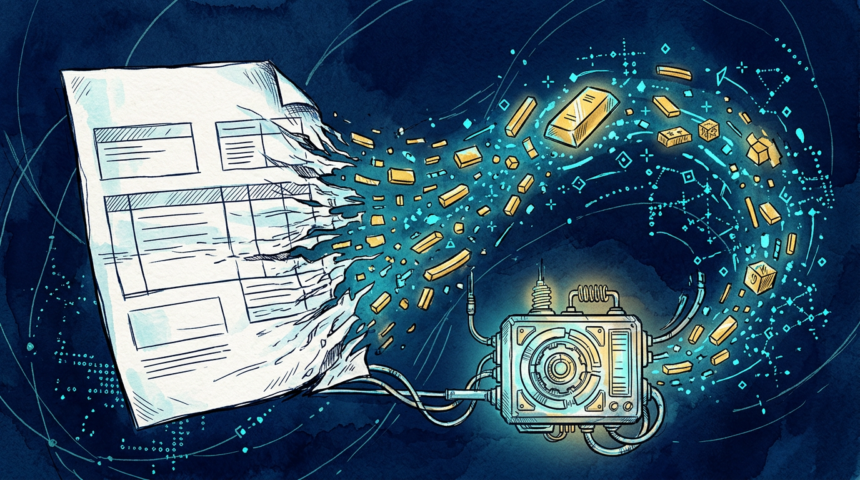
Cloudflare released a preview of Clairic, the first of what it calls System One extraction models. It reads an input, plus up to four images, and returns typed values: an invoice total, a due date, an order number, a probability range.
The model runs on Workers AI as @cf/cloudflare/clairic, and the company says it intends to publish the weights openly.
The design choice is the point. Clairic does not generate text, so it cannot mistype a digit or invent a plausible answer. It makes a single forward pass, charges only for input tokens, and typically responds in under a second.
What comes back
Each field returns a value of the declared type, a confidence score and, for extracted text, a character span pointing back into the source. Estimates arrive as a median with an 80% interval inside bounds the caller sets.
When the model cannot find an answer it returns null rather than guessing – the failure mode that plagues JSON extraction pipelines built on frontier LLMs.
The economics behind it
Cloudflare argues that most structured-output calls sent to large models are the same shape repeated forever, and that paying reasoning plus output tokens for each one is waste. Its comparison benchmark reports a claims pipeline running substantially faster and cheaper than an all-LLM approach.
The market is moving this way. Labs that spent years racing to the biggest model now ship small, purpose-built ones, because those are what buyers can put into production without a budget review.