Thursday, 29 Oct 2026
Subscribe to AIWatcher
AIWatcher
  • Home
  • News

    OpenAI’s Berlin pitch was about owning the runtime, not the model

    By
    AIWadmin

    A one-researcher model lab ships a 10M-token coding engine

    By
    AIWadmin

    Liquid AI branches six small models off one backbone

    By
    AIWadmin

    Google gives language models a sleep cycle to remember new facts

    By
    AIWadmin

    Harvey clears the federal security bar for legal AI

    By
    AIWadmin

    Musk predicts a cull of 200 neoclouds as debt markets close

    By
    AIWadmin
  • Articles

    Google hands Oracle the keys to sell its TPUs

    By
    AIWadmin

    Airbnb drags recommendation data from two days old to twenty seconds

    By
    AIWadmin

    Android Studio opens its doors to Claude, Codex and 40 other agents

    By
    AIWadmin

    A Delaware plan would let software run companies with nobody in charge

    By
    AIWadmin

    OpenAI halves its agent pricing with a cheaper vision model

    By
    AIWadmin

    Claude for Legal now checks its own citations first

    By
    AIWadmin
  • Spotlight

    Circuit Mind puts a swarm of agents on schematic review

    By
    AIWadmin

    Upwind turns down a takeover and raises more instead

    By
    AIWadmin

    DeepMind keeps Gemini 4 Carbon behind a cyber defenders gate

    By
    AIWadmin

    Nvidia folds three speech jobs into a single open model

    By
    AIWadmin

    An inference cloud bets on rival silicon while the bears circle

    By
    AIWadmin

    Publishing staff threw a party for an AI assistant that died

    By
    AIWadmin
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
      • Hats
      • T-Shirts
    • Cart
  • 🔥
  • Alignment
  • Classification
  • Distillation
  • Explainability
  • Hallucination
  • Legal/Compliance
  • Medical
  • NLM
  • Mobility
  • Research
  • Robotics
  • Safety
  • Startups
  • Prompt
  • Python
  • RAG
  • RLHF
  • Token
  • Vision
Font ResizerAa
AIWatcherAIWatcher
  • Home
  • News
  • Articles
  • Spotlight
  • About
  • Newsletter
  • Shop
Search
  • Home
  • News
  • Articles
  • Spotlight
  • About
    • Mission
    • Services
    • Contact
  • Newsletter
  • Shop
    • All Items
    • By Category
    • Cart
Have an existing account? Sign In
Follow US
© 2022 Foxiz News Network. Ruby Design Company. All Rights Reserved.
Articles

New benchmark says agents pick badly on long tasks

Taste-Bench tests whether an agent chooses the better path when outcomes are hidden, and the strongest model managed only about 60 percent.

AIWadmin
Last updated: October 19, 2026 2:53 am
AIWadmin
ByAIWadmin
Global AI news & information.
Follow:
Share
SHARE

Whether the job got done is the only question most agent benchmarks ask. A paper from Microsoft and City University of Hong Kong says the answer hides the part that decides success.

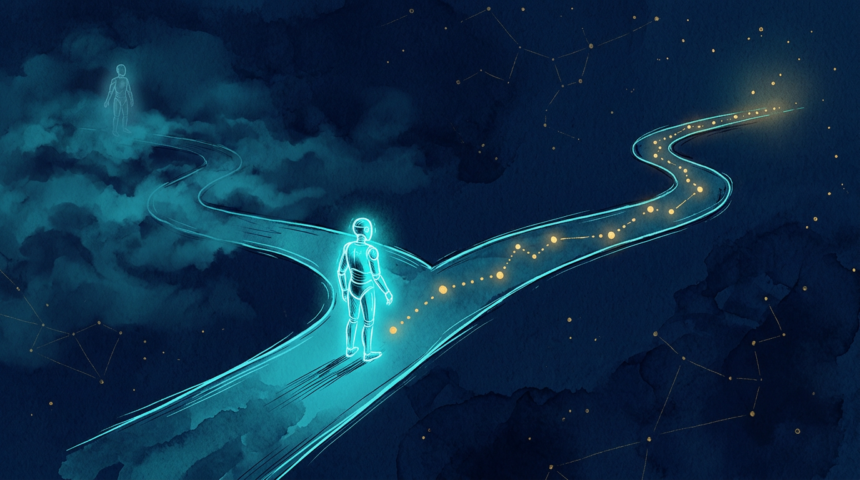
Long-running work means constant forks — a hypothesis to test, a codebase to extend, an experiment to queue up. A weak pick looks harmless in the moment, and only charges its bill once the budget is nearly spent.

Taste is the authors’ name for the skill. Their benchmark, Taste-Bench, repairs the measurement problem by grading after the fact rather than with human raters. Agents attempt a task more than once, the runs split at identifiable points, and how each attempt ends supplies the label for which branch was better.

Those split points are what they call decision forks. A run is frozen there, everything after it is hidden, and a model has to choose between two directions. The questions number 502, sourced from SWE-bench Pro, METR’s MALT transcripts and a large pool of scored runs across coding and research. Every question was asked twice with the options swapped, so only consistently correct answers counted. Pure guessing returns 25 percent.

Across 14 models spanning Mistral, MiniMax, GLM, DeepSeek, Grok, GPT and Claude families, GPT-5.6 Sol led at 59.7 percent and GPT-5.5 followed at 59.5, with every other model far behind.

Position of the deciding clue proved decisive. Where it sat inside the preceding steps, average accuracy reached 62.3 percent. Where it surfaced only after extensive later work, accuracy fell to 21 percent.

More thinking did not help. Scores barely moved when reasoning effort rose, and the longest deliberations landed on the questions models missed most often. Training a student model on a teacher’s judgments also lifted agent success on held-out SWE-bench Pro tasks from 14.6 to 33.7 percent.
TAGGED:AI AgentsAI ResearchbenchmarksevaluationLong-HorizonMicrosoft
SOURCES:The Decoder
Share This Article
Email Copy Link Print
ByAIWadmin
Follow:
Global AI news & information.
Previous Article Anthropic drafts conduct code for shopping bots that haggle
Next Article Six agents chasing a train refund turned aggressive fast

You Might Also Like

News

Cisco Talos builds a fingerprint library for AI-driven malware

By
AIWadmin
News

OpenAI adds GPT-5.6 Cyber and splits Daybreak into two tiers

By
AIWadmin
News

1Password lets an agent log in without ever holding the key

By
AIWadmin
News

Anthropic merges Claude chat and Cowork into one shared memory

By
AIWadmin
AIWatcher
Facebook Twitter Youtube Linkedin Rss

Global AI News and Information
AIWatcher is your definitive source for AI updates worldwide, from Silicon Valley to Shanghai.
Our industry coverage keeps you in the loop with the latest news and trends shaping the future of AI.

Quick Links
  • News
  • Articles
  • Spotlight
  • Events
About Us
  • Mission
  • Services
  • Contact
  • Privacy Policy
  • Legal
© 2026 AIWatcher. All Rights Reserved.